AI Visibility Audit: A 450-Answer Sheet and a Tool Rule
An AI visibility audit checks whether ChatGPT, Perplexity, Gemini and Google's AI features can reach, mention, cite and correctly describe your brand, using repeated runs of 30 prompts instead of one query.
By Harjot Chopra, Co-Founder, PageLens.ai · Updated 14 Oct 2026
Key takeaways
- An AI visibility audit is 30 buyer prompts run three times on each of five engines (450 answers), scored for mention, citation and accuracy. One query is not a baseline.
- Check crawler access first; it takes about ten minutes. None of 20 large software sites we checked on October 14, 2026 blocked OAI-SearchBot or PerplexityBot, but your own file may differ.
- Score each engine separately. Engines lean on different source types, and a blended score hides the cause of a gap.
- Do the first pass by hand. Move to a tracker when you will not repeat the 450-answer pass at least monthly (our recommendation).
In this article
- 1What is an AI visibility audit, and how is it different from an SEO audit?
- 2How many runs does an audit need before the numbers are stable?
- 3Can AI crawlers reach your priority pages?
- 4What goes on the audit sheet?
- 5Why do ChatGPT, Perplexity, Gemini and Google AI Mode give different results?
- 6How do you turn audit findings into fixes?
- 7Should you audit by hand or use a tracker?
- 8Frequently asked questions
A full audit pass is 450 answers, while the usual audit is one screenshot. A screenshot records one draw from a spread of possible answers. SparkToro's January 2026 study found less than a 1-in-100 chance that ChatGPT or Google's AI returns the same list of brands twice.
A checklist tells you what to look at; only repeated runs tell you whether a result is stable. So the decision that matters most is how many times you ask. Access, content and source fixes only make sense once the answers you are reading are stable.
This page gives you the sheet we recommend: 30 prompts, five engines, three runs each, with scoring rules and a diagnosis table. It also covers the ten-minute access check, why engines disagree, and a time-and-cost model for choosing between a hand audit and a tracker. PageLens.ai publishes this page and sells one of those trackers, so we say where it fits.
What is an AI visibility audit, and how is it different from an SEO audit?
An AI visibility audit tests whether selected answer engines can access, understand, cite and accurately describe your brand for the prompts your buyers use. A search engine optimization (SEO) audit asks whether your pages can be found and ranked. The AI audit adds the answer itself.
An AI visibility audit is not a generic checklist and it is not a one-time chatbot query. It joins the site conditions we can inspect with the answers buyers actually receive, then asks why a brand was absent, inaccurately described, mentioned without a citation, or displaced by another source.
A traditional SEO audit still matters because it checks whether pages can be found, crawled, indexed, and ranked. This audit adds the answer layer: prompt-specific mentions, citations, sentiment (whether the answer's tone toward your brand is positive, neutral or negative), accuracy, source gaps, and the work needed to change them.
The engines in scope are ChatGPT, Perplexity, Gemini and two Google surfaces: AI Overviews, the AI summaries Google shows on Search results pages, and AI Mode, Google's conversational search tab.
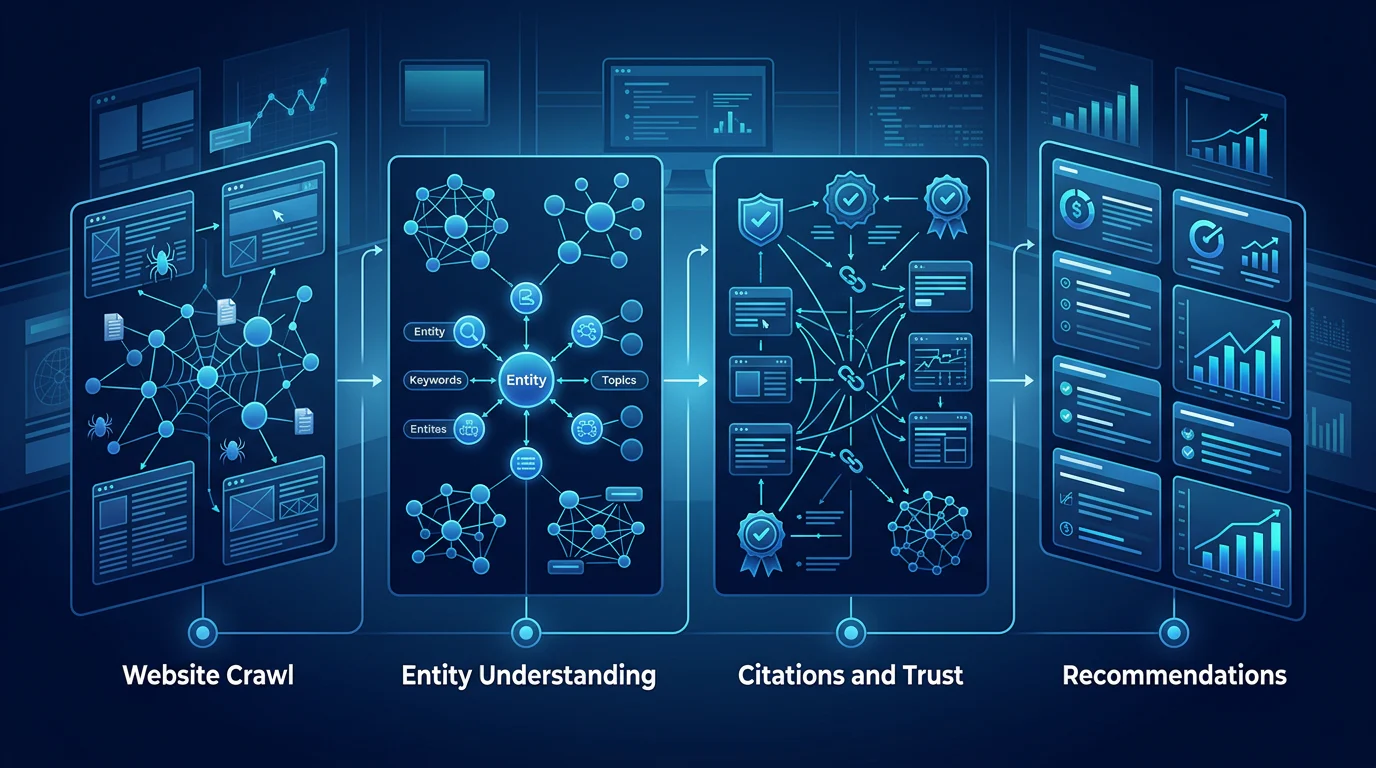
Three terms appear in the table below. The robots.txt file sits at the root of a site and tells crawlers which paths they may fetch. A WAF (web application firewall) is an edge filter that can block a crawler even when robots.txt allows it. An entity is a clearly identified brand, product or person that a machine can tell apart from similar names. Rendered HTML is the page after JavaScript has run.
| Audit Layer | Question To Answer | Evidence To Capture | Useful Output |
|---|---|---|---|
| Crawl | Can relevant systems retrieve priority pages? | robots.txt, status codes, rendered HTML, WAF evidence | Accessible, blocked, or unverified |
| Understand | Is the brand and product information unambiguous? | visible claims, entity markup, identifiers, source consistency | Entity and factual gaps |
| Cite | Is there a concise, supported passage worth using? | direct answers, tables, sources, dates, third-party references | Citation-ready page or content gap |
| Recommend | Does the brand appear accurately for buyer prompts? | mentions, citations, sentiment, answer language, source gaps | Owner-based remediation plan |
The important distinction is causality. A page can be crawlable and still never appear in an answer. A brand can be mentioned but described incorrectly. A source can be cited without contributing the recommendation a buyer sees. Our audit keeps those outcomes separate, so teams do not mistake technical eligibility for earned visibility.
The stakes are measurable on the click side. Pew Research Center followed 900 US adults' browsing in March 2025 and, across 68,879 Google searches, found that users clicked a traditional result link in 8% of visits when an AI summary appeared and 15% when it did not. When the answer absorbs the click, being named in it is what remains.
How many runs does an audit need before the numbers are stable?
Run every prompt three times on each engine: 30 prompts × 5 engines × 3 runs is 450 answers per pass. Three runs is our recommendation, not a published threshold. Its job is to separate prompts where your brand appears reliably from prompts where it appears by chance.
The reason is variance. The SparkToro study used 12 prompts and 2,961 runs from 600 volunteers on ChatGPT, Claude and Google AI Overviews. It found less than a 1-in-1,000 chance that the same list comes back in the same order, and Claude was only slightly more consistent than the others. Our own research points the same way: in Citation Research Study 008, we re-asked 5 questions on four engines (20 answers) and brand lists moved by about a quarter on the second asking. That is a small sample, but it points the same way.
Two consequences follow:
- Do not record position. Order changes on almost every run, so "we were third" describes one draw. Record the share of runs in which you were mentioned.
- Read three runs coarsely. With three runs, a prompt scores 0, 1, 2 or 3 out of 3. Treat 3 of 3 as reliable, 1 or 2 of 3 as unstable and 0 of 3 as absent. A move from 0 of 3 to 3 of 3 after a fix is readable. A move from 2 of 3 to 3 of 3 is not, and you need many more runs to detect small changes.
Different trackers given identical prompts can also return different answers, as Digiday reported in May 2026. Whatever method you use, ask how many runs sit behind each number.
Can AI crawlers reach your priority pages?
Usually yes: ChatGPT search uses OAI-SearchBot, Perplexity uses PerplexityBot, and Google's AI features use normal Googlebot access, with no separate crawler. Confirm each in about ten minutes, because a blocked page cannot be cited.
Review discovery, user-requested retrieval, and training controls separately. OpenAI's crawler documentation lists OAI-SearchBot for surfacing sites in ChatGPT search, GPTBot for training generative models, and ChatGPT-User for actions a person triggers, where robots.txt rules may not apply. Perplexity's documentation describes PerplexityBot as a search crawler not used for foundation-model training, and Perplexity-User as an agent that generally ignores robots.txt because a person asked for the fetch. Google states that no additional requirements apply to appear in AI Overviews or AI Mode beyond standard Search technical requirements.
The next table refers to a CDN (content delivery network), the service that sits in front of many sites and can filter crawlers, alongside the WAF defined above.
| Surface | Access Evidence To Review | Important Caveat |
|---|---|---|
| ChatGPT Search | OAI-SearchBot rules, page access, CDN and WAF response | Training and search access are separate decisions |
| Google AI Features | Googlebot access, indexability, snippet controls, rendered text | No separate AI crawler is required |
| Perplexity Search | PerplexityBot rules, published IP handling, WAF logs | User-requested fetches can behave differently |
Read robots.txt by user agent and URL path, then record the rule that actually matches. The Robots Exclusion Protocol specifies that the most-specific matching rule wins, so a blanket verdict can conceal an allow or disallow rule on the exact page that matters. The robots standard also distinguishes unavailable responses from server failures, another reason to retain the raw evidence.
To print every group that applies to these bots, plus the User-agent: * group that covers any bot without its own, run this with GNU awk (gawk):
curl -s https://yourdomain.com/robots.txt | awk 'BEGIN{IGNORECASE=1} /^user-agent:/{p=($0 ~ /(\*|oai-searchbot|gptbot|chatgpt-user|perplexitybot)/)} p'
Then test your priority URL against the printed Allow and Disallow lines. Pass: the longest matching rule is an Allow, or no Disallow matches the URL. Fail: the longest matching rule is a Disallow. When an Allow and a Disallow match with equal length, the standard says the Allow is used.
Also inspect page-level robots directives, X-Robots-Tag headers, authentication gates, challenge pages, and soft errors. A clean robots.txt file cannot override a CDN rule that blocks a legitimate crawler, and a successful browser visit cannot prove what a crawler received.
Treat llms.txt, a proposed plain-text index of a site's key pages, as implementation status only. Google's AI features documentation states that you do not need new machine-readable files, AI text files or special structured-data markup to appear in AI Overviews or AI Mode.
What goes on the audit sheet?
Each row is one prompt, on one engine, on one day. The columns record whether you were mentioned, cited and described accurately, plus who else appeared. Our recommended 30-prompt mix is 8 category, 8 comparison, 8 recommendation and 6 use-case prompts, which covers the path from learning to deciding.
| Cluster | Prompts | Example pattern |
|---|---|---|
| Category | 8 | "What is [category] and who offers it?" |
| Comparison | 8 | "[Your brand] vs [competitor] for [use case]" |
| Recommendation | 8 | "Best [category] for [buyer type] in the US" |
| Use-case | 6 | "How do I [job to be done] with [category]?" |
Write prompts in the wording buyers use, not your internal product names. Use the same location and signed-in state for every run, and spread the three runs over at least two days.
Row columns: prompt text, cluster, engine, run number, date, location, interface, full answer text, brands named, your domain cited (yes or no), cited domains, accuracy label.
Scoring rules:
- Mentioned: pass if your brand name appears in the answer text. Mention rate for a prompt and engine is the runs mentioned divided by 3.
- Cited: pass if your domain appears in the answer's source list.
- Accurate: pass if price, product description, location and key claims match your own pages. Label the answer correct, mixed or wrong. A cited link is a source to inspect, not proof that the answer is right, so accuracy is scored separately.
- Stable: 3 of 3 is reliable, 1 or 2 of 3 is unstable, 0 of 3 is absent.
Then roll rows up by cluster, per engine, never averaged across engines:
| Prompt Cluster | Mentioned? (runs out of 3) | Cited? (runs out of 3) | Accurate? | Cited-Source Gap | Next Check |
|---|---|---|---|---|---|
| Category | 0 to 3 | 0 to 3 | Correct, mixed, or wrong | Which source was preferred? | Entity and authority evidence |
| Comparison | 0 to 3 | 0 to 3 | Correct, mixed, or wrong | Missing proof or outdated framing | Comparison page and third-party facts |
| Recommendation | 0 to 3 | 0 to 3 | Correct, mixed, or wrong | Missing qualifier or source | Extractable answer passage |
| Use-case | 0 to 3 | 0 to 3 | Correct, mixed, or wrong | Which source answers the task instead? | Task coverage and conflicting brand information |
Why do ChatGPT, Perplexity, Gemini and Google AI Mode give different results?
Engines draw on different kinds of sources, so one blended score hides the cause of a gap. In Citation Research Study 007, a community platform (Reddit, YouTube or Quora) was cited in 117 of 150 Google AI Mode answers and 3 of 150 ChatGPT answers.
Our research at Citation Research asked 150 everyday decision questions on four engines in October 2026 (one run each, logged out). The India-asked results for community-platform citations were:
| Engine | Answers citing Reddit, YouTube or Quora |
|---|---|
| ChatGPT | 3 of 150 |
| Perplexity | 73 of 150 |
| Gemini | 29 of 150 |
| Google AI Mode | 117 of 150 |
The same study asked 50 questions from the US: 64 of 200 US-asked answers cited a community platform, against 61 of 200 from India. Community sources are not a feature of one market; the spread by engine is what to plan around. In Study 008, Perplexity also returned identical sources for 60 of 60 questions asked from India, the UK and the US, while Google AI Mode localized the most. Run your sheet from the location your buyers search in.
Our inference from this: if a competitor beats you on AI Mode but not on ChatGPT, check whether community threads and videos name them before you rewrite your own pages. If you are absent everywhere, look at your own pages and entity facts first.
How do you turn audit findings into fixes?
Match each pattern on the sheet to a cause, then to an owner. A finding becomes actionable only when it names the evidence, the affected page or prompt, a responsible owner, a proposed change and a validation test.
| Pattern on the sheet | Likely cause | Check |
|---|---|---|
| 0 of 3 on every engine, bot blocked | Access | robots.txt group, CDN and WAF logs |
| 0 of 3, access fine | Content or entity gap | Compare your page to the pages that are cited, using a content gap analysis |
| Mentioned, never cited | Source gap | Which domains are cited instead |
| Cited, described wrong | Conflicting facts | Page copy, markup and third-party profiles |
| Strong on one engine only | Source-type difference | Community and review sources on the weak engines |
| Finding | Owner | Proposed Fix | Validation Test | Monitoring Date |
|---|---|---|---|---|
| Priority page blocked at edge | Engineering | Adjust approved WAF or CDN policy | Verify genuine access evidence and rerun prompts | After deployment and recrawl |
| Conflicting product claim | Content And Product | Reconcile visible copy and markup | Compare page, markup, and source records | Next prompt run |
| Weak answer passage | Content And SEO | Add direct answer and supporting proof | Validate rendered page and answer clarity | After publication |
| Repeated third-party source gap | PR And Growth | Improve factual consistency and authority coverage | Track cited-source mix by prompt cluster | Monthly review |
Structured data helps clarify meaning when it is accurate and visible on the page, but it is not a citation trigger. Fix conflicting facts before adding markup.
Rerun the same prompts after a material change, with the same engine, locale, and collection conditions where possible. Compare what changed in the answer, citation set, and source gap, then record whether the result supports the original hypothesis. For month-over-month comparison, keep the prompt set fixed and track AI citations over time. To see whether visits follow, track AI traffic in GA4, Google's free web analytics tool. Google reports clicks from AI Overviews and AI Mode inside the Web search type in Search Console's Performance report, so they are not broken out on their own.
Should you audit by hand or use a tracker?
Do the first pass by hand, then move to a tracker when you will not repeat the 450-answer pass at least monthly. That threshold is our recommendation. The sheet's value comes from repetition, and one pass already means opening, copying and scoring 450 answers.
Our model: at an assumed 2 minutes per answer, 450 answers is 900 minutes, or 15 hours per pass. Repeating monthly means 15 hours a month. If your time costs $50 an hour (an assumption; use your own rate), that is $750 a month, against $299 a month on our Launch plan. Time your first ten answers and rescale: at 1 minute per answer the pass is 7.5 hours.
A hand audit is free apart from time, and it teaches you which prompts matter. It breaks down on repetition, because each retest after a fix costs another pass. Trackers, including ours, automate the collection. Whichever you consider, ask four things: which engines are covered, how many runs sit behind each score, whether the location is settable, and whether you can export the raw answers and cited sources. Our AI visibility tool trial checklist turns those into a 14-day test.
How we do it at PageLens.ai. We run the prompts you choose on a schedule, store each answer with the sources it cited, and show brand sentiment, the pages models quote and human and AI crawler traffic in one dashboard. As of October 2026, in US dollars with monthly billing, our plans are:
| Plan | Price | Tracked prompts | Answers | Engines |
|---|---|---|---|---|
| Launch | $299 a month | 100, checked weekly | 300 a week | ChatGPT, Google AI Mode, Perplexity |
| Growth | $699 a month | 100, checked daily | 500 a day | Adds Gemini and Grok |
| Enterprise | $1,499 a month | 200, checked daily | 1,400 a day | Adds Claude and Copilot |
Annual billing saves 8%, and every plan has unlimited users. Our model of the sheet on Launch: 30 prompts × 3 engines is 90 answers per weekly check. Each weekly check uses 90 of Launch's 300 weekly answers, so three runs take three weeks (270 answers in total). Gemini needs our Growth plan or above, and Google AI Overviews still needs manual collection. See our pricing for the full plans.
If you want a first look before spending a day on the sheet, our free AI visibility audit takes your domain and returns a visibility score, what ChatGPT, Gemini and Perplexity say about you, and the competitors they name instead, in about 30 seconds, with no signup or credit card. To see this sheet running on your own prompts, Book a demo.
Track your AI visibility without the manual work
Frequently asked questions
Yes. The sheet above costs time, not money: 30 prompts, five engines and three runs each. For a quicker look, our free AI visibility audit needs only your domain and returns a result in about 30 seconds.
Sources
- 1.SparkToro: AI brand recommendation inconsistency study (January 2026)
- 2.Pew Research Center: Google users are less likely to click on links when an AI summary appears (July 2025)
- 3.Google Search Central: AI features and your website
- 4.OpenAI: crawlers and user agents
- 5.Perplexity: crawlers and user agents
- 6.IETF: RFC 9309, Robots Exclusion Protocol
- 7.Citation Research Study 007: Reddit, YouTube and Quora in AI citations
- 8.Citation Research Study 008: Asked from India, answered from America
- 9.Digiday: Marketers question expensive AI visibility tools as inconsistent results fuel skepticism (May 2026)
- 10.Our robots.txt spot check of 20 software sites, October 14, 2026 (method described above)