How to Rank in Perplexity: A Reach-and-Cite Test
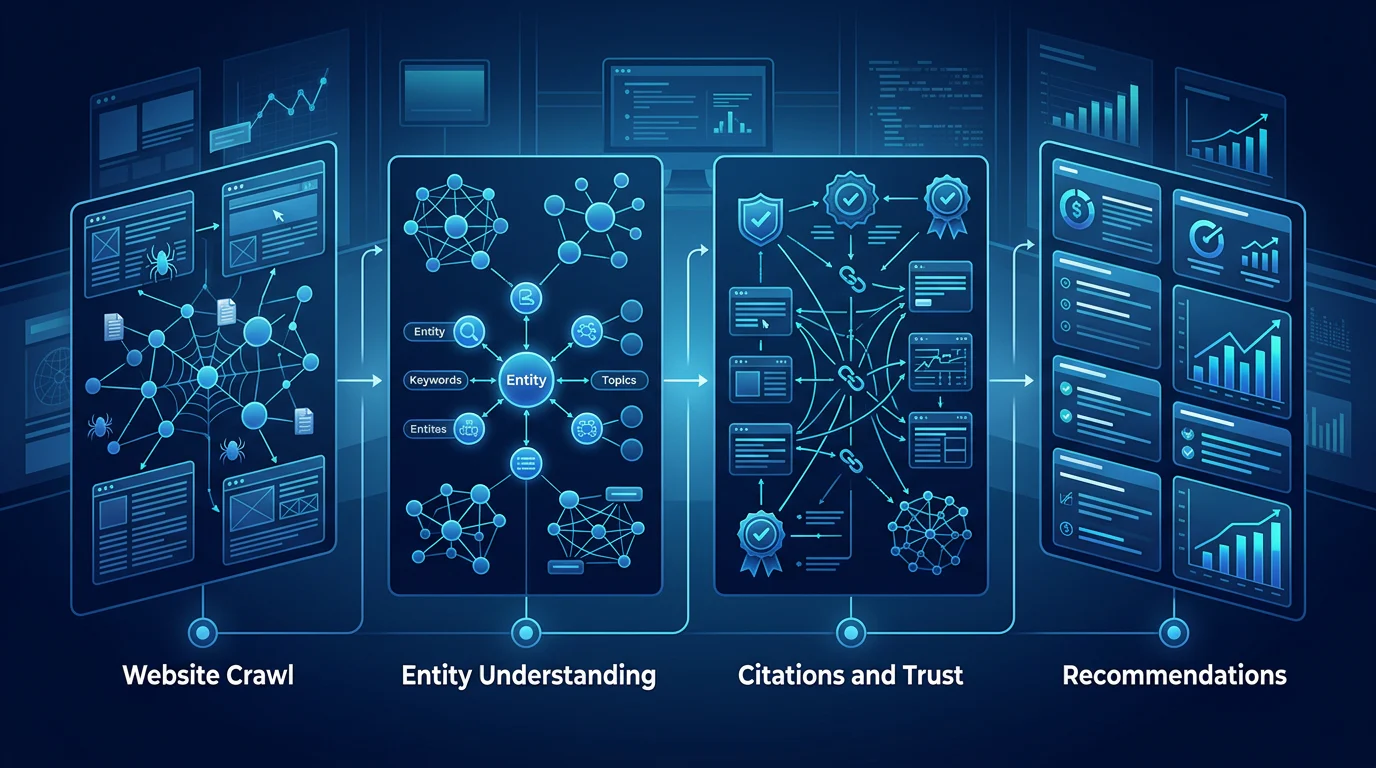
Perplexity SEO comes down to two checks: whether PerplexityBot can reach your pages, and whether Perplexity cites them across repeated runs of the same buyer prompts. Test both before rewriting anything.
By Harjot Chopra, Co-Founder, PageLens.ai · Updated 14 Oct 2026
Key takeaways
- To rank in Perplexity, first confirm PerplexityBot can fetch your pages, then measure citations over repeated runs of a fixed buyer-prompt panel. Access makes a page eligible. It does not earn the citation.
- Check the answers, not only robots.txt. Some sites that block PerplexityBot still appear in its citations.
In our Citation Research study, Perplexity cited at least one community platform in nearly half of 150 decision-question answers. Third-party presence is its own work queue.
- Run each prompt three times, logged out, and count a page as cited only if it appears in at least two of the three runs.
In this article
- 1What is Perplexity SEO, and how is it different from Google SEO?
- 2What do PerplexityBot and Perplexity-User each do, and what controls them?
- 3Is a robots.txt check enough to know whether Perplexity can cite you?
- 4What does Perplexity cite when buyers ask a decision question?
- 5How do you run the Perplexity reach-and-cite test?
- 61. Does robots.txt allow PerplexityBot on your key pages?
- 72. Does your server answer PerplexityBot with a 200?
- 83. Is the answer in the HTML the server sends?
- 94. How do you build the buyer-prompt panel and run it?
- 105. Which domains does Perplexity cite, and how stable are your citations?
- 11What should you fix first when Perplexity skips your pages?
- 12How do you measure Perplexity visibility over time?
- 13Frequently asked questions
Perplexity cited at least one community platform, such as Reddit or LinkedIn, in 73 of 150 decision-question answers in our Citation Research study (fieldwork October 2026). A page can be crawlable and well written and still not be among the sources that shape an answer.
The questions are practical. Did a firewall rule block Perplexity by accident? Why does the answer change every time you ask? Does a crawl ever turn into a citation? Google Analytics answers none of them, and neither does a screenshot of one answer.
This page gives you a test that does. It starts with a robots.txt script, moves to a fixed panel of buyer prompts run three times each, and ends with a decision table that turns misses into tasks.
It draws on a robots.txt check we ran across well-known sites and on that study. Run it once for a baseline, then weekly, and log every material page change so you can tie shifts to edits.
What is Perplexity SEO, and how is it different from Google SEO?
Perplexity SEO is the work of making your pages reachable by Perplexity's crawler and worth citing in its answers. It overlaps heavily with Google SEO, because crawlability, useful content and authority carry over. The difference is the result you measure: a citation inside an answer, not a position in a list.
PerplexityBot is "designed to surface and link websites in search results on Perplexity". In our Citation Research Study 007, Perplexity's 150 answers carried 1,504 citations, about 10 sources per answer, so expect roughly ten slots per answer for similar questions. Each slot goes to a passage that answers the buyer's specific constraint.
For the wider comparison, read GEO vs SEO: what actually changes.
What do PerplexityBot and Perplexity-User each do, and what controls them?
PerplexityBot indexes pages so Perplexity can surface and link them in search results, and it follows robots.txt, the file at the root of a site that tells crawlers what they may fetch. Perplexity-User visits a page when a user's request needs it and generally ignores robots.txt rules. Neither is used to train foundation models, the large AI models behind chat assistants (Perplexity crawler documentation).
Perplexity publishes the IP addresses both bots use: PerplexityBot and Perplexity-User. As of 14 October 2026 the first file lists 8 IPv4 address ranges (prefixes) and the second lists 4. The files carry creation dates of 7 February 2025 and 17 October 2025, so pull them fresh rather than copying addresses into a rule once.
The documentation advises matching the user-agent string and verifying the IP address together. It also says crawler-setting changes may take up to 24 hours to appear, and web application firewall (WAF) updates can take longer. Log the change date before you rerun the prompt panel.
A firewall or bot-management rule can block Perplexity without anyone editing robots.txt. Cloudflare's new-domain defaults, below, are one way this happens.
Cloudflare's August 2025 report adds a reason to test rather than assume. It reported 3 to 6 million requests a day from an undeclared crawler, against 20 to 25 million from the declared ones, and delisted Perplexity as a verified bot. A Cloudflare-fronted site can therefore treat Perplexity differently from other crawlers with no robots.txt change.
From 15 September 2026, new domains onboarding to Cloudflare get updated defaults. Search crawlers are allowed. Training and Agent crawlers, defined as automated activity acting in real time on a person's behalf, such as chat fetch bots, are blocked on pages that display ads. Perplexity-User's job matches that Agent description. If your domain is new to Cloudflare and runs ads, test it. That is our inference, not a Cloudflare classification.
Is a robots.txt check enough to know whether Perplexity can cite you?
No. robots.txt only records what PerplexityBot may crawl. In our check of 42 well-known sites on 14 October 2026, 20 disallow PerplexityBot at the root, including Reddit and LinkedIn. Perplexity cited both in our research (next section). Use robots.txt as an access setting and read the answers for the verdict.
Method: we fetched www.<domain>/robots.txt for each site, decoded compressed responses, and parsed each file with Python's urllib.robotparser. We confirmed every file contained robots rules, because a challenge page or an undecoded file parses as "allowed". We then tested whether PerplexityBot may fetch /. We chose the sites ourselves, so this is not a random sample. It cannot see content delivery network (CDN) or firewall blocks.
| Group (domains tested) | Sites | Disallow PerplexityBot at `/` |
|---|---|---|
| News and publishing: nytimes, theguardian, washingtonpost, wsj, cnn, bbc, reuters, bloomberg, wired, theverge, cnet, zdnet, apnews, investopedia | 14 | 14 |
| Community and review: reddit, linkedin, quora, yelp | 4 | 4 |
| Software, SEO-tool and marketplace: hubspot, semrush, ahrefs, moz, g2, shopify, salesforce, zendesk, atlassian, mailchimp, notion, slack, stripe, webflow | 14 | 0 |
| Other: forbes, techcrunch, businessinsider, medium, wikipedia, tripadvisor, healthline, webmd, nerdwallet, nature | 10 | 2 (forbes, nature) |
| Total | 42 | 20 |
Seventeen of the 20 blocks name PerplexityBot in a rule. Reddit, Reuters and WSJ are caught by a blanket rule instead. If your robots.txt is clean and you are still absent from answers, content and third-party presence are more likely causes than access.
What does Perplexity cite when buyers ask a decision question?
In nearly half of answers, at least one cited source was a community platform, though community platforms were only 11.7% of Perplexity's citations. In our Citation Research study of 150 decision questions, Perplexity cited one in 73 answers (48.7%): Reddit in 42 and LinkedIn in 25 (Study 007).
The questions covered 10 topics, including business software, in Indian-English phrasing ("Should I…", "Is it worth…"). They went to four engines, with 600 answers routed from India and 200 from the US. Community platforms were 11.7% of Perplexity's 1,504 citations, so the remainder came from other sources.
Perplexity returned the same source list in India, the UK and the US for all 60 questions in Study 008. The authors caution that this may reflect how the collection service reaches Perplexity rather than what every signed-in user sees. Run your panel logged out, since account history can change what you see.
Community platforms are a minority of Perplexity's citations but turn up in about half of these answers. The topics skew consumer, so the mix may differ for B2B buyers. Tally your own panel in step 5 rather than borrowing ours.
How do you run the Perplexity reach-and-cite test?
Run five steps: three access checks, a fixed buyer-prompt panel, and a tally of what Perplexity cites. Each check has a pass and a fail. Work in this order, because a content fix is wasted on a page the crawler cannot fetch.
1. Does robots.txt allow PerplexityBot on your key pages?
Open yourdomain.com/robots.txt, then run this:
import urllib.robotparser as rp
site = "https://yourdomain.com"
pages = ["/", "/pricing", "/your-key-page"]
parser = rp.RobotFileParser(site + "/robots.txt")
parser.read()
for agent in ["PerplexityBot", "Perplexity-User", "GPTBot", "Googlebot"]:
    for path in pages:
        print(agent, path, parser.can_fetch(agent, site + path))
Pass: True for PerplexityBot on every key page. Fail: any False, so find the specific or catch-all rule causing it. Read the Perplexity-User line for information only, since it generally ignores robots.txt.
Also confirm in a browser that the file shows the PerplexityBot rules you expect. A file the script cannot decode, or a challenge page, parses as "allowed".
2. Does your server answer PerplexityBot with a 200?
Request a key page with the PerplexityBot user-agent string:
curl -s -o /dev/null -w "%{http_code}\n" -A "Mozilla/5.0 AppleWebKit/537.36 (KHTML, like Gecko; compatible; PerplexityBot/1.0; +https://perplexity.ai/perplexitybot)" https://yourdomain.com/your-key-page
Pass: 200. Fail: 403, 429, 503 or a challenge page. If your firewall also verifies IP addresses, this request from your own machine can fail even though the real bot passes. In that case, check your WAF log for requests from the prefixes in the PerplexityBot file. Allow those addresses alongside the correct user agent.
Our free Cloudflare AI crawler check fetches your homepage as each AI crawler, live, if you want a second opinion.
3. Is the answer in the HTML the server sends?
Run curl -s https://yourdomain.com/your-key-page | grep -c "a phrase from your answer". Pass: 1 or more. Fail: 0, which means the answer appears only after a client-side script loads. Check the canonical URL and login requirements the same way:
curl -s https://yourdomain.com/your-key-page | grep -i canonicalshould return the page's own URL.- A page that redirects to a login fails.
A blocked crawler needs a technical fix. A crawlable page with weak proof needs a content fix. Keep those work queues separate.
4. How do you build the buyer-prompt panel and run it?
Choose 20 to 30 questions that reflect decisions buyers make before choosing a provider. We use this range as a practical starting panel for repeatable citation tracking. Include prompts from five groups:
- Category: "What is the best [category] software for [audience]?"
- Use case: "Which [category] tool helps [audience] do [job]?"
- Comparison: "How does [option A] compare with [option B] for [constraint]?"
- Problem: "How can I solve [pain] without [constraint]?"
- Implementation: "What should a [role] look for before buying [category]?"
For every prompt, save these fields:
- Prompt ID
- Exact wording
- Buyer role
- Buying stage
- Market and language
- Business priority
- Evidence source
Use customer calls, sales objections, support tickets, win-loss interviews, public reviews, and site-search terms first. Keep generated variations in a separate test queue. Prompt research covers how to choose the prompts worth tracking.
Assign one owned page to each prompt. Pass: every prompt has a page and an evidence source. Fail: a prompt with no owned page goes straight to the action table below.
Run every prompt three times under the same conditions: logged out, with the same country, language and Perplexity mode throughout the reporting period. Three runs is the smallest number where a majority exists. At 20 prompts that is 60 saved answers, and at 30 it is 90.
For each answer, save:
- Exact prompt
- Timestamp
- Full answer text
- Every displayed citation URL
- Every brand named
- Your brand's description
- Recommendation wording
- Competitor wording
- The page or source that supports each claim
Do not save only a screenshot, a score, or a referral count. A useful record keeps the answer and source context together.
5. Which domains does Perplexity cite, and how stable are your citations?
Count domains across all runs, not brand names. Label every cited page with one source type:
- Official product or pricing page
- First-party research
- Independent review
- Software directory
- Comparison page
- News coverage
- Community discussion
- Educational guide
Then write one sentence beside each source: "This source supplied the answer to which buyer question?" A directory may establish category options, an official pricing page may establish cost, and a customer story may establish implementation proof.
Count your domain as a stable citation only if it appears in at least 2 of the 3 runs for a prompt. That threshold is our recommendation, not a published standard. A single-run appearance is unstable and should not be counted as a win.
A citation alone does not mean Perplexity recommends the cited company. Perplexity can cite a source while summarizing, comparing, or cautioning about its product. Record the answer's exact language so you can tell the difference.
What should you fix first when Perplexity skips your pages?
Fix access first, then missing or weak pages, then third-party gaps. A repeated miss should create one clear task with an owner. This table maps what the test found to the next action:
| Signal | Evidence | Next action | Owner |
|---|---|---|---|
| Bot blocked | Step 1 or 2 fails, or the WAF rejects the crawler | Update the access rule | Technical owner |
| Answer not in server HTML | Step 3 returns 0 | Render the answer server-side | Technical owner |
| No owned page | No relevant answer exists | Publish answer page | Content lead |
| Weak owned page | Answer lacks proof | Add primary evidence | Subject expert |
| Rival wins repeatedly | Rival source answers the constraint | Build stronger evidence | Content lead |
| Only third parties cited | Directories, communities or news fill the answer | Earn presence on those sources | PR or community lead |
| Stale fact | Old price or capability | Refresh source page | Product marketer |
This table is a prioritization tool, not a promise that one edit creates one citation. Prioritize high-value prompts where the missing evidence is concrete and your team can publish or fix it.
For a weak page, start each relevant section with a self-contained answer. Name the company, product, use case, limit, and evidence directly. Avoid vague openings such as "this solution" or "many businesses." Add the evidence a buyer needs to decide:
- Current product capabilities
- Plan names and prices, when price matters
- Named integrations
- Implementation requirements
- Geography or compliance limits
- Source methodology for original data
- Clear dates on changing facts
How do you measure Perplexity visibility over time?
Use the same prompts each week and track five prompt-level metrics. Changing the panel too often makes a content improvement look better or worse than it was.
- Brand mention rate: prompts naming your brand ÷ tested prompts.
- Owned citation rate: prompts citing your domain ÷ tested prompts.
- Recommendation rate: prompts where the answer names your brand as a pick, or among a short list of picks (not merely mentioned, cautioned against or cited) ÷ tested prompts.
- Competitor win rate: prompts where a named competitor is recommended and you are not ÷ tested prompts.
- Source mix: domains and page types Perplexity cites most often.
Apply the 2-of-3 rule from step 5 to rates 1 to 4, so a prompt counts only when the result holds in at least two of its three runs. Establish a baseline, log every material page change, then retest the unchanged panel weekly. When a result shifts, compare the full answer, cited URLs, recommendation language, and competitor context before assigning a new task. A disappearing citation may coincide with a page change, a competitor's new evidence, or a changed source mix, so do not treat it as a single-page problem.
To see what ChatGPT says about your brand before building a panel, run the Free AI Visibility Audit, and use prompt research to choose which prompts to track.
This is the loop we run at PageLens.ai. On our Launch plan, $299 a month as of October 2026, we track 100 prompts weekly across ChatGPT, Google AI Mode and Perplexity, with 300 AI answers a week and competitor, citation and sentiment analysis. It also includes 25 content pieces a month. Our pricing page lists the engines on each plan. If you want the panel run for you and the misses turned into content actions, Book a demo.
Have PageLens.ai run your Perplexity prompt panel
Frequently asked questions
Not reliably. A robots.txt block stops PerplexityBot from crawling your pages, but it does not control what appears in answers. Reddit and LinkedIn both disallowed PerplexityBot in our 14 October 2026 check, yet Perplexity cited both in Study 007.
Up to 24 hours, according to Perplexity's crawler documentation. Firewall updates can take longer to propagate. Log the change date, then rerun your prompt panel only after that window has passed.
No. Crawler requests appear in server and firewall logs, not in Google Analytics 4 (GA4), which records browser sessions. People who click a Perplexity citation can appear as perplexity.ai referrals, and Track AI Traffic in GA4 shows how to isolate them.
Sources
- 1.Perplexity crawler documentation
- 2.PerplexityBot IP list
- 3.Perplexity-User IP list
- 4.Cloudflare: Perplexity is using stealth, undeclared crawlers, Cloudflare, 4 August 2025
- 5.Cloudflare changelog: new options to manage AI traffic, Cloudflare
- 6.Citation Research Study 007, Citation Research, October 2026
- 7.Citation Research Study 008, Citation Research, October 2026
- 8.Python urllib.robotparser documentation, Python
- 9.PageLens.ai pricing, PageLens.ai, October 2026