AI Citation Tracking: How Many Answers Make a Number Real
AI citation tracking logs which sources AI answers link to. About 100 answers per engine make a citation rate readable to within roughly ten points; under 30 answers shows direction only.
By Harjot Chopra, Co-Founder, PageLens.ai · Updated 14 Oct 2026
Key takeaways
- AI citation tracking is logging, for a fixed set of prompts, which URLs each AI answer links to. Collect about 100 answers per engine before reading a citation rate to within roughly ten points. Treat fewer than 30 as a direction, not a result.
- Report each engine separately. Engines cite very different sources, and a blended rate hides that.
- Start free. Google Search Console's Generative AI performance report shows impressions in Google's AI features, and our free audit gives a first look at what ChatGPT, Claude, Gemini, Perplexity and Google AI say about you.
- Compare tools by answers analyzed per month and the count of answers behind each rate, not by headline prompt counts. As of October 2026, our Launch plan is $299 per month for 100 prompts a week on three engines.
In this article
- 1What is AI citation tracking, and what does it count?
- 2How many answers do you need before an AI citation rate means anything?
- 3Why do citation numbers differ between engines and between tools?
- 4What can you measure for free before you pay for an AI citation tracker?
- 5How do you log AI citations in a sheet you can trust?
- 6How do we run citation tracking at PageLens.ai?
- 7What does a tracked prompt cost across AI citation tracking tools?
- 8Which tests should an AI citation tracker pass before you pay?
- 9Frequently asked questions
One engine cited community platforms such as Reddit, YouTube or Quora in 117 of 150 answers, and another cited them in 3. Those were Google AI Mode, Google's conversational AI search tab, and ChatGPT in our October 2026 study of 150 decision-style questions (Citation Research Study 007). The questions were phrased for India, so read the counts as a demonstration, not a US benchmark.
A result from one engine says little about another. Answers also change between runs of the same engine, so one screenshot of an engine naming your brand shows a single draw from a spread of possible answers. Marketing and search engine optimization (SEO) leads are still asked to report a position. A report you can defend states how many answers sit behind each rate and how those answers were collected.
Below: what counts as a citation, how to size a sample, why engines and tools disagree, a log sheet you can copy, what tracking costs, and the tests we would run on any tracker, ours included.
What is AI citation tracking, and what does it count?
AI citation tracking is running a fixed set of prompts on a schedule across AI engines and logging every source link in each answer. It counts citations, meaning linked sources inside an answer. It keeps them separate from mentions and referral clicks.
Terms, used the same way for the rest of this page:
- Prompt: a question you ask an engine, such as "best accounting software for a five-person agency".
- Answer: one engine's response to one prompt on one run. Answers are your unit of counting, not prompts. The number of answers behind a rate is its denominator.
- Citation: a link in the answer to a page on your domain. A mention is your brand named in the text, linked or not. A referral is a visitor who clicks through to your site.
A brand can be mentioned without being cited, and cited without ever being clicked. The rates that follow:
- Citation rate: answers that cite your domain ÷ answers logged for that engine.
- Mention rate: answers that name your brand ÷ answers logged for that engine.
- Cited URLs: which of your pages earned the links.
How many answers do you need before an AI citation rate means anything?
You need about 100 answers per engine to read a citation rate to within roughly ten percentage points. Under 30 answers, treat the rate as a direction only. Every answer either cites you or does not, so a rate is a sample, and small samples are wide.
The table shows the range the true rate could plausibly sit in for the same observed rate at each sample size.
| Answers per engine | Cited in 20% of answers: plausible true rate | Cited in 50% of answers: plausible true rate |
|---|---|---|
| 10 | 6% to 51% | 24% to 76% |
| 20 | 8% to 42% | 30% to 70% |
| 30 | 10% to 37% | 33% to 67% |
| 50 | 11% to 33% | 37% to 63% |
| 100 | 13% to 29% | 40% to 60% |
Our calculation, run in October 2026: we used the Wilson score interval, a standard way to turn a sample rate into a plausible range for the true rate, at 95% confidence (z = 1.96 is the multiplier for that confidence level). It assumes every answer is an independent draw. Repeated runs on one engine on the same day may not be independent, so the real uncertainty is somewhat wider than shown.
Two rules follow from the same math (our model, not an official figure):
- Answers needed for a margin of error: n = 1.96² × 0.25 ÷ margin², rounded up. The 0.25 is the worst case, a true rate of 50%. That gives about 43 answers for ±15 points, 97 for ±10 and 385 for ±5.
- Calling a change real: between two periods, the gap must exceed 1.96 × √(2 × p × (1 − p) ÷ n), where p is the rate and n is the answers per period. With 30 answers in each period, rates near 50% must move about 25 points, and rates near 20% about 20 points. With 100 answers each, those thresholds fall to about 14 and 11 points. If the two intervals in the table overlap, treat the change as unproven.
Our recommendation is to get there by pooling, which means combining answers into one rate. Pool 30 or more prompts per theme across four weekly runs, which gives 120 or more answers per engine. Report one rate per engine per theme only once a theme reaches 100 answers per engine. Until then, report one pooled rate per engine across all themes. Read single prompts only for direction. Pooled prompts differ in difficulty, and a four-week window assumes your underlying rate holds still, so start a fresh window when you ship a major change.
Why do citation numbers differ between engines and between tools?
Engines cite different kinds of sources, and tools collect answers in different ways, so one blended citation rate hides more than it shows. Report each engine separately, fix the location you sell in, and keep one collection method over time.
On the engine gap, Study 007 asked 150 questions per engine. Answers that cited a community platform (Reddit, YouTube or Quora):
| Engine | Answers citing a community platform |
|---|---|
| Google AI Mode | 117 of 150 (78%) |
| Perplexity | 73 of 150 (49%) |
| Gemini | 29 of 150 (19%) |
| ChatGPT | 3 of 150 (2%) |
Limits of that study:
- The questions were phrased for India.
- Each question ran once per engine on October 5, 2026, logged out (without signing in), through a scraping service.
- 24 AI Mode answers and 49 Gemini answers had no captured sources.
A second study, Study 008, asked 60 buying questions from India, the UK and the US (720 answers, also October 5, 2026). Perplexity returned identical source lists in all three countries, while ChatGPT and Google AI Mode changed with location. In its repeat check, 5 questions were asked again on all four engines. Across those 20 repeated answers, brand lists overlapped 74% of the time, so about 26% of brands changed between runs of the same question. That is a small sample, but it shows why one run is not a baseline.
Tools add their own spread. They gather answers through different methods: application programming interfaces (APIs, direct data feeds from the engine), scraping (reading the chat interface automatically) or synthetic data (modeled rather than live answers). The same query can therefore return very different responses (Digiday, December 2025). For example, a score of 14% in one tool and 22% in another may reflect collection methods, not a difference in your brand's standing. Do not compare scores across vendors.
What can you measure for free before you pay for an AI citation tracker?
Two free sources cover a lot: Google Search Console's Generative AI performance report and a one-off audit run. Neither gives you a weekly rate by engine, but together they show whether Google's AI features show your links and what the other engines say about you.
As of August 31, 2026, Google reports that the Generative AI performance report is available to all websites worldwide. It shows impressions, meaning how many times links to your site were shown in AI Overviews (the AI summaries above regular Google results) and AI Mode. Sites without enough impressions may see no data, and tables are capped at 1,000 rows. It covers Google only and shows nothing about competitors. Pull it first, because it is Google's own count. Google also states that no third-party tool has access to its internal ranking or AI systems. Trackers measure what answers show, not why a page was chosen.
For the other engines, our free AI Visibility Audit takes your domain and runs buyer prompts on ChatGPT, Claude, Gemini, Perplexity and Google AI in about 30 seconds, with no signup. It reports a visibility score, sentiment and the competitors the engines recommend instead. One run per prompt per engine is a small sample: a 20% rate from 10 answers, for example, could be anywhere from 6% to 51%. Use the audit to see which competitors and sources appear, not to set a baseline.
How do you log AI citations in a sheet you can trust?
Log one row per answer, with the engine, location and collection method on every row, and calculate rates only from those rows. A sheet like this is enough to start. It also checks any tool's numbers later.
- Choose 30 or more prompts
Use comparison, alternative, best-of and fit questions that buyers ask. Our guide to choosing AI prompts worth tracking covers how to pick them.
- Run each prompt once per engine, per weekKeep the same location and the same account state (logged out is simplest).
- Log each answer in a rowwith these columns:
- Calculate over four-week windowsEach rate is rows with Y ÷ rows for that engine in the window, with the interval from the table beside it. At 30 prompts, a window holds 120 answers per engine. Read single weeks as direction.
| Column | What to enter |
|---|---|
| Date | Run date |
| Engine | ChatGPT, Perplexity, Gemini, Google AI Mode |
| Location | The market you sell in |
| Prompt ID | Your own number, so prompts stay comparable |
| Run number | 1 for the first run that week |
| Collection method | Manual, direct data feed (API) or tool name |
| Brand named | Y or N |
| Your domain cited | Y or N |
| Cited URL | The page on your domain, if any |
| Competitor domains cited | Each domain, separated by commas |
| Tone | Positive = recommended or ranked first; neutral = listed without a view; negative = warned against |
Thirty prompts on three engines is 90 answers a week, which is 30 per engine. That is the practical limit for logging by hand.
How do we run citation tracking at PageLens.ai?
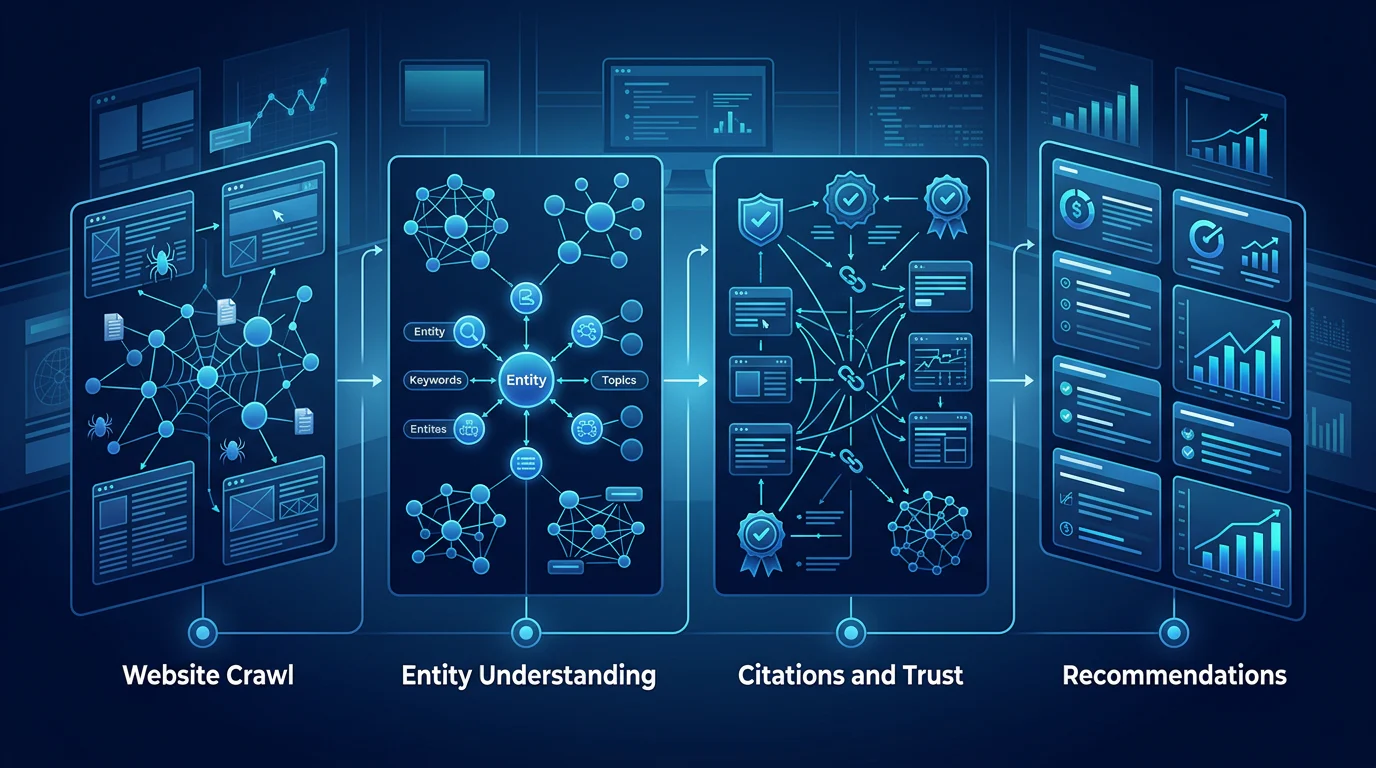
We run every tracked prompt on every engine in your plan on a fixed schedule, analyze each answer, and report citations by engine and by page. The answers-analyzed count is prompts × engines × frequency, so you can check our math.
- Launch: 100 prompts weekly on ChatGPT, Google AI Mode and Perplexity, which is 300 answers analyzed per week (100 × 3).
- Growth: 100 prompts daily on those three plus Gemini and Grok, which is 500 answers per day (100 × 5).
- Enterprise: 200 prompts daily on seven engines, including Claude and Copilot, which is 1,400 answers per day (200 × 7).
On Launch, each engine receives about 100 answers per weekly run. That is near the 100-answer row in the table, so a pooled weekly rate per engine is readable to roughly ten points at worst. Our plans also report share of voice (your citations as a share of all citations in the tracked answers), sentiment and citations earned per page, week over week, and every plan has unlimited users. Prices are on our pricing page.
What does a tracked prompt cost across AI citation tracking tools?
As of October 2026, published monthly prices work out to between $1.22 and $7.50 per tracked prompt across the plans below. The figures compare only when engines and checking frequency match, and here they do not. We publish this page, and our plans are in the table.
| Plan | Price per month | Prompts | Price per prompt | Engines in the base plan |
|---|---|---|---|---|
| $29 | 15 | $1.93 | ChatGPT, Google AI Overviews, Perplexity, Microsoft Copilot | |
| Otterly Standard | $189 | 100 | $1.89 | Same four |
| Otterly Premium | $489 | 400 | $1.22 | Same four |
| $99 | 25 | $3.96 | Prompt tracking on Google AI Mode and ChatGPT | |
| PageLens.ai Launch | $299 | 100 | $2.99 | ChatGPT, Google AI Mode, Perplexity |
| PageLens.ai Growth | $699 | 100 | $6.99 | Adds Gemini and Grok |
| PageLens.ai Enterprise | $1,499 | 200 | $7.50 | Seven engines |
Price per prompt is the monthly price ÷ prompts. Otterly tracks daily on all three plans and sells Claude, Google AI Mode and Gemini as paid add-ons. Our Launch plan checks weekly; Growth and Enterprise check daily.
Cost per answer is a fairer yardstick where the count is published. Our model for our plans, at monthly billing:
- Launch: $299 ÷ 1,300 answers (300 × 52/12) is about $0.23 per answer.
- Growth: $699 ÷ 15,000 answers (500 × 30 days) is about $0.05.
- Enterprise: $1,499 ÷ 42,000 answers (1,400 × 30) is about $0.04.
Annual billing is 8% lower on Launch, Growth and Enterprise. Price per prompt rises with Growth while price per answer falls, because Growth runs daily on five engines. Ask any vendor for answers analyzed per month and divide.
Which tests should an AI citation tracker pass before you pay?
A tracker should pass five tests you can run in an afternoon: it shows the denominator, shows the raw answers, splits by engine, repeats within the sampling range and documents how it collects answers. Run them on any tool, ours included.
| Test | How to run it | Pass | Fail |
|---|---|---|---|
| Denominator | Open one engine's report | The answer count sits beside each rate | A score with no count |
| Raw answers | Open three logged answers | Full answer text and cited URLs are visible | Only a summary |
| Engine split | Look at the citation rate | One rate per engine | One blended rate |
| Repeat | Run the same prompts twice on one day | The gap between the two runs' rates is below 1.96 × √(2 × p × (1 − p) ÷ n), the change rule above, with p the average rate and n the answers per run | A larger gap |
| Collection | Ask how answers are gathered and which location is used | Method and location are documented and fixed | Unknown or changing |
The repeat test is our recommendation. A tool that swings more than the sampling math allows is either noisy or changing how it collects. For a longer trial, use the 14-day AI visibility tool trial checklist.
To see this run on your own prompts, Book a demo.
See citation tracking run on your own prompts
Frequently asked questions
Partly. Google says a page must be indexed and eligible to show in Search with a snippet to appear as a supporting link in its AI features, with no additional technical requirements. SEO groundwork still matters. What changes is measurement, because answers vary by run and need sampling.
Not automatically. A citation is a link, and a click is a separate event. Google's report counts impressions only, so measure referral visits in your analytics. Our guide to tracking AI traffic in GA4 shows how to group those visits.
Sources
- 1.Citation Research Study 007: Reddit, YouTube and Quora in AI citations, October 2026
- 2.Citation Research Study 008: AI answers from India, the UK and the US, October 2026
- 3.Google Search Console Help: Generative AI performance report
- 4.Google Search Central: AI features and your website
- 5.Google Search Central: AI optimization guide
- 6.Digiday: WTF is AI citation tracking?, December 2025
- 7.Otterly pricing, October 2026
- 8.Semrush AI Visibility Toolkit documentation, October 2026
- 9.PageLens.ai pricing, October 2026
- 10.PageLens.ai Free AI Visibility Audit