AI Visibility Platform: 12 Questions to Ask Before You Buy
Choose an AI visibility platform by how openly it explains where its numbers come from. Put twelve method questions, drawn from the Interactive Advertising Bureau’s 2026 framework, to every vendor in writing before you pay, then trace each figure to a saved answer.
By Harjot Chopra, Co-Founder, PageLens.ai · Updated 13 Nov 2026
Key takeaways
- Choose an AI visibility platform by its written answers to twelve method questions, not by its feature list. A vendor that will not answer them has told you what you need to know.
- Read a platform’s score as a rate over many runs of each question. If you cannot open the saved answers behind a number, do not rely on it.
- For a buying decision, ask for IAB’s stricter “decision-grade” disclosure. The lighter “directional” level only suits watching trends.
- You can test any vendor’s figure yourself in two days by running five of your own buyer questions on the platform and on the live engines.
In this article
- 1What is an AI visibility platform, and why do two of them score one brand differently?
- 2Which 12 questions should you ask any AI visibility platform before you pay?
- 31. Which engines and model versions does it measure, and are they reported separately?
- 42. How many prompts does it run, and where do they come from?
- 53. Do the prompts cover more than one kind of question?
- 64. How many times is each prompt run?
- 75. How often are prompts run?
- 86. How are answers collected, and does the method follow the engines' terms?
- 97. Under what conditions are answers collected: live web retrieval and country?
- 108. How much do results vary, and how does the vendor know?
- 119. Are mentions and citations counted separately, and how is a mention detected?
- 1210. Does it separate accurate mentions from wrong ones?
- 1311. What happens to your history when an engine changes?
- 1412. Can you open the raw answer behind any number?
- 15Is "directional" data enough, or do you need "decision-grade"?
- 16How can you test an AI visibility platform's numbers yourself?
- 17What should an AI visibility platform let you do with the numbers?
- 18Which of the twelve questions can PageLens.ai answer in writing today?
- 19What should you do before you pay for an AI visibility platform?
- 20Frequently asked questions
More than 20 companies now sell AI visibility measurement. In August 2026 the Interactive Advertising Bureau (IAB), the advertising industry's trade body, said their different methods can produce different answers for the same brand. A feature list cannot settle that. Two platforms can both show a tidy score while counting different things.
The score also moves for reasons that have nothing to do with the vendor. A SparkToro and Gumshoe.ai study reported in January 2026 ran 2,961 prompts, each 60 to 100 times per platform, and nearly every response differed in the brands listed, their order and the length of the list. A number built on a handful of runs mostly reflects chance.
Below are twelve questions to put to any platform, a test you can run on a vendor's figure, and how PageLens.ai answers them. The test checks whether each number in a platform's report traces back to a saved answer that you can open and read for yourself.
What is an AI visibility platform, and why do two of them score one brand differently?
An AI visibility platform is software that asks answer engines your buyers' questions on a schedule, records which brands and pages come back, and reports rates such as how often you are named. Two platforms score one brand differently because they pick different questions, collect answers differently and run each question a different number of times.
Some terms, used the same way throughout:
- An answer engine is a tool such as ChatGPT, Perplexity or Google AI Mode that answers in prose and cites sources.
- A prompt is the question a buyer types into one.
- A mention is an answer that names your brand.
- A citation is an answer that links to your site as a source. An answer can do one without the other, so a sound platform counts them separately.
The study was run by SparkToro and Gumshoe.ai on ChatGPT, Claude and Google's AI Overviews, with AI Mode used when Overviews did not appear, and hundreds of volunteers took part. Gumshoe.ai sells AI tracking tools. Their finding was that the list of brands changed run to run, while the share of runs in which a brand appeared was steadier than any single position.
The IAB's framework does not rank vendors or certify anyone. It does set out what a vendor should disclose, and it adds that where a provider will not disclose a required item, "that absence should itself be treated as a signal." The sheet below applies that rule.
Which 12 questions should you ask any AI visibility platform before you pay?
Ask the twelve questions below in writing, and score each answer pass or fail. Questions 1 to 11 adapt IAB's disclosure list and criteria matrix. Question 12 is our recommendation. A vendor that fails several has not shown you how its number is made.
1. Which engines and model versions does it measure, and are they reported separately?
Pass: it names each engine and model version and reports each engine on its own. Fail: you get one blended score. IAB requires platform coverage with model version (PDF p. 28), and results per platform (PDF p. 24), because engines behave differently.
2. How many prompts does it run, and where do they come from?
Pass: a stated count, the categories they cover, and whether they are written by the vendor, drawn from real search volume or observed from user behavior. Fail: "thousands of prompts" with no breakdown. IAB treats fewer than 50 queries in a program as "exploratory", too few to characterize a category (IAB criteria matrix, PDF pp. 24–25).
3. Do the prompts cover more than one kind of question?
Pass: the vendor discloses the mix of informational ("what is X"), comparison ("X vs. Y"), recommendation ("best X for Y") and transactional ("where to buy X") prompts, and for important decisions lets you filter by type. IAB asks for at least two types for trend work and all four for decisions (IAB criteria matrix, PDF pp. 24–25). Fail: only "best tool" questions.
4. How many times is each prompt run?
Pass: a stated number of runs per prompt and how consistency is judged. Fail: one answer per prompt behind each figure. IAB asks vendors to disclose responses per query (IAB criteria matrix, PDF pp. 24–25). For how many runs make a rate dependable, see our guide to AI citation tracking.
5. How often are prompts run?
Pass: weekly or more often if you are allocating budget. Fail: monthly collection used to justify a budget decision. IAB calls monthly or quarterly collection suitable for trend monitoring and weekly or more frequent suitable for budget allocation (IAB criteria matrix, PDF pp. 24–25).
6. How are answers collected, and does the method follow the engines' terms?
IAB groups collection into active query simulation, passive panel observation and platform-native data. Ask the vendor which it uses and whether it follows each platform's terms. Pass: the vendor says which, and whether it follows the terms. Fail: no answer. IAB also says results from different collection architectures should not be presented as equivalent (IAB, PDF p. 29).
7. Under what conditions are answers collected: live web retrieval and country?
Pass: it states whether live web retrieval was on, off or both, names the country and language the questions were asked from, and does not blend runs made under different settings. Fail: no setting or country stated. An answer written with live search can cite pages that an answer without it cannot, and the same question asked from another country can return different sources.
IAB requires providers to disclose the retrieval setting (IAB, PDF p. 29) and the geographic origin of queries, with results reported per market (IAB, PDF pp. 33–34). In our Citation Research Study 008, asked from India, four engines cited American sites 3.4 times as often as Indian ones (720 answers from India, the UK and the US).
8. How much do results vary, and how does the vendor know?
Pass: it defines acceptable variation, reports confidence levels and documents how it checks consistency. IAB's decision-grade tier asks for variation ranges within a seven-day window (IAB criteria matrix, PDF pp. 24–25). Fail: a bare percentage with no stated margin.
9. Are mentions and citations counted separately, and how is a mention detected?
Pass: separate counts, plus a plain description of how it matches your brand name and handles lookalike names. Fail: one "visibility" number that mixes both.
10. Does it separate accurate mentions from wrong ones?
Pass: it reports hallucinated mentions (a brand or claim the engine invented) and factually wrong descriptions separately, checked against facts you supply. IAB requires that comparison to use a brand-supplied source of truth (IAB, PDF p. 30). Fail: every mention counted as good news.
11. What happens to your history when an engine changes?
Pass: the vendor documents when it re-baselines (resets the starting point a trend is measured from after an engine update) and what triggered it, so a trend line does not break silently (IAB, PDF p. 30). Fail: a chart that jumps with no explanation.
12. Can you open the raw answer behind any number?
Our recommendation: every figure should click through to the saved answer text, with engine and timestamp. Pass: you can open it. Fail: a number you cannot trace. This is the question that makes the other eleven checkable.
Is "directional" data enough, or do you need "decision-grade"?
For choosing and paying for a platform you should ask for decision-grade disclosure, not just directional. IAB defines directional data as fit for trend monitoring and internal briefing. Decision-grade data is, in IAB's words, required before making any budget or strategy decisions, and its criteria matrix lists provider selection among those decisions.
In practice the two tiers differ on exactly the points in the sheet. Compare them side by side, per IAB's criteria matrix (PDF pp. 24–25):
| Criterion | Directional | Decision-grade |
|---|---|---|
| Intent coverage | At least two types | All four types, results available by type |
| Cadence | Monthly or quarterly | Weekly or more often |
| Variation | Provider documents typical variation | Acceptable range defined within seven days, confidence levels reported |
Our reading: a free one-off check is exploratory at best, which is fine for a first look. A platform you will report to your leadership on should be able to answer questions 4, 5 and 8 in detail. Sub-50-prompt programs are exploratory by IAB's definition, so count prompts before you trust any chart.
How can you test an AI visibility platform's numbers yourself?
Run five of your own buyer questions through the platform, run the same five on the live engines, and repeat the next day. Check that every brand and source in the platform's report appears in a saved answer.
- Write five questionsA buyer in your category would ask these, mixing "best X for Y", "X vs Y" and "alternatives to X".
- Run them in the platformUse a trial or demo, and note which brands are named and which URLs are cited.
- Run the same five yourself
Use the engines the platform covers, in a fresh session each time. Our free engine checkers show the live answer, its sources and whether your brand is named for ChatGPT, Gemini, Perplexity, Grok and Copilot.
- Repeat the next dayExpect the brand lists to differ somewhat. That variation is normal and is why a single answer proves little.
- CompareOur recommendation for the pass mark: Pass: at least 3 of the 5 questions show one or more of the same brands in both the platform's saved answers and your own runs, and every brand in the platform's report appears in a saved answer. Fail: a reported brand or source appears in no saved answer.
For a quick first look, our free AI Visibility Audit asks buyer prompts across ChatGPT, Claude, Gemini, Perplexity and Google AI with no signup and takes about 30 seconds. Treat it as an exploratory first look, below even IAB's directional tier, and not as decision-grade evidence.
For a larger sheet that uses repeat runs across engines, see our AI visibility audit guide.
What should an AI visibility platform let you do with the numbers?
The twelve questions test whether a platform's numbers can be trusted. They do not test what you can do with them, because IAB's framework covers measurement only and leaves optimization and attribution out of scope (IAB, PDF p. 7). These four checks are ours, not IAB's, and they matter once the numbers pass.
- Can you see why you are missing? Pass: it shows the pages and domains each engine cited, so you know what to beat. Fail: a score with no sources behind it.
- Can you act on a gap? Pass: it connects a gap to a fix, whether that is a page brief or a published page on your own domain. Fail: a dashboard that ends at the chart.
- Can you show what moved? Pass: it re-reads the same prompts after you publish and shows the change in mentions and citations, with the run count behind it. Fail: a before-and-after that rests on a few answers.
- Is the competitor set yours? Pass: you choose the brands you are compared against, and the vendor states how the category is defined, which IAB requires for share of voice (IAB, PDF p. 16). Fail: a preset leaderboard you cannot change.
Price is the last check. Compare the cost per prompt per engine, not the plan price, because the same plan price can buy very different prompt and engine counts.
Which of the twelve questions can PageLens.ai answer in writing today?
PageLens.ai publishes written answers on engines, prompts and how we count mentions and citations. Ask us about the rest, including runs per prompt and re-baselining, on a demo. We publish this page and we are one of the platforms the sheet applies to, so you should hold us to it.
- Engines (question 1): we read each answer engine on its own. In our Citation Research Study 007, Google AI Mode cited a community platform such as Reddit, YouTube or Quora in 117 of 150 answers, and ChatGPT in 3 of 150. Each question was run once per engine in October 2026 from India, so rates will differ for your category. Launch tracks ChatGPT, Google AI Mode and Perplexity. Growth adds Gemini and Grok. Enterprise adds Claude and Copilot, seven engines in all, and the Agency plan covers all engines. No plan tracks Google AI Overviews as its own engine. Plan details are on our pricing page.
- Prompts (question 2): we read your site and generate the questions buyers in your category ask. See prompt research.
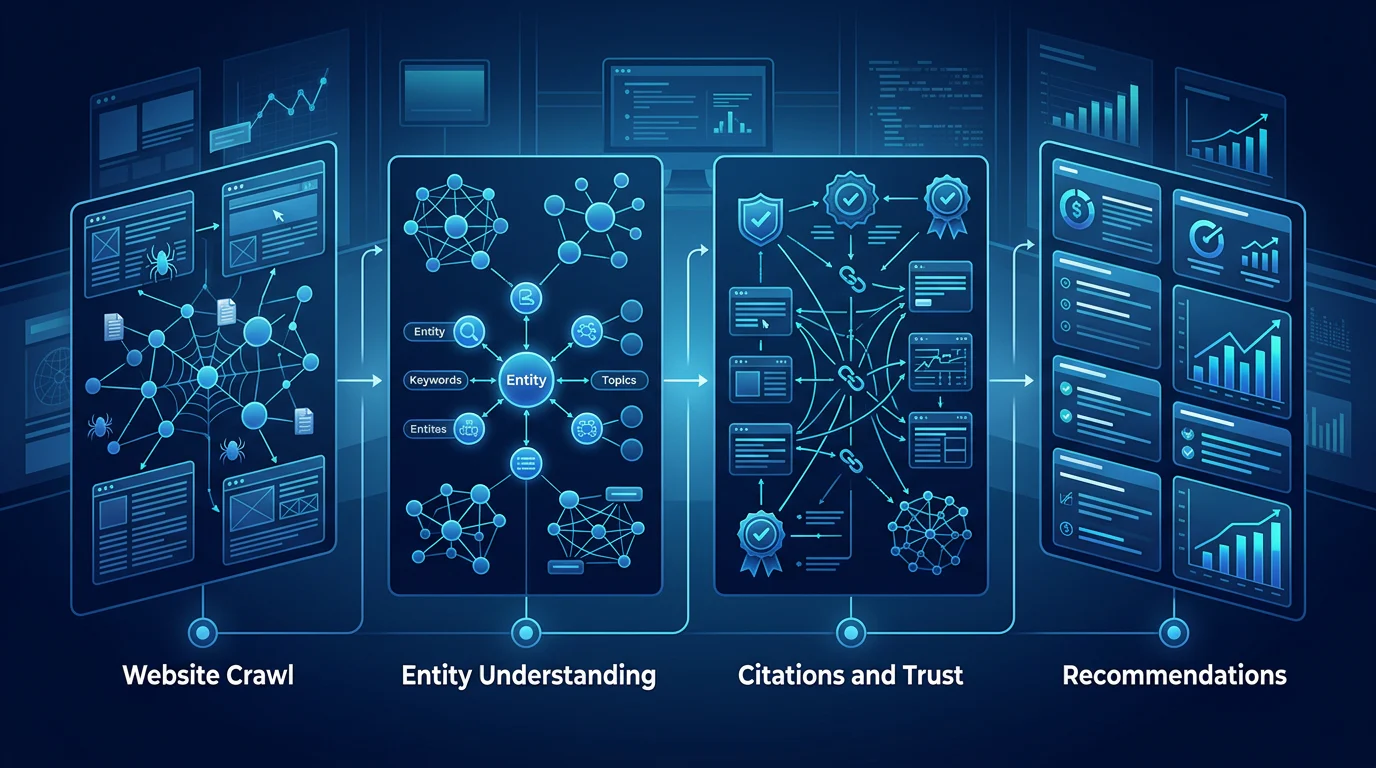
- Mentions and citations (question 9): we calculate visibility, the share of answers that name your brand, and citation rate, the share that cite your site, as separate measures. How PageLens.ai Works shows each formula.
- Acting on the numbers: the content engine writes pages for the gaps it finds, the CMS publishes them on your domain and analytics shows whether they get cited.
For a wider market view, see AI Visibility Tools: 10 Compared on Price, Engines, Publishing.
What should you do before you pay for an AI visibility platform?
Choose by the evidence a vendor will put in writing, and set your bar before the first demo. If a platform cannot open the saved answer behind a number, treat that number as exploratory, whatever the dashboard says. If it can, check that it states its prompt count, runs per prompt, cadence and variation, because those four decide whether a figure can support a budget.
In the next 48 hours, send the twelve questions to your shortlist in writing and run the five-question test on the two vendors that reply most plainly. Drop any platform whose reported brands you cannot find in a saved answer. Keep the rest for a trial.
If you want to test PageLens.ai against this rule, book a demo and put the twelve questions to us.
Put all twelve questions to PageLens.ai
Frequently asked questions
Sources
- 1.IAB Releases 'Measuring Visibility in the AI Era'
- 2.Measuring Visibility in the AI Era (PDF): scope (PDF p. 7), share of voice (PDF p. 16), criteria matrix (PDF pp. 24–25), required disclosures (PDF pp. 28–30), geographic provenance (PDF pp. 33–34)
- 3.AI Recommendations Change With Nearly Every Query: SparkToro (a secondary report of the SparkToro and Gumshoe.ai study)
- 4.Study 007: Reddit, YouTube and Quora in AI citations
- 5.AI recommendation lists repeat less than 1% of the time: Study, Search Engine Land, 2026
- 6.Study 008: AI answers from India, the UK and the US, Citation Research, fieldwork October 2026