
Tools for Monitoring Brand Mentions Across AI Engines
Compare tools for monitoring brand mentions across AI engines by prompts, evidence, citations, sentiment, reporting, and procurement requirements.
Tools for Monitoring Brand Mentions Across AI Engines
In an analysis of 68,879 Google searches, 18% produced an AI summary, a clear reason brands need to know what answer engines say before a prospect reaches their site, according to Pew Research Center.
Tools for monitoring brand mentions across AI engines repeatedly run defined buyer prompts, capture whether your brand and competitors appear, preserve the response and citations, and show changes over time. The right choice depends on prompt control, engine mode, repeat frequency, raw-response evidence, localization, reporting, and governance, not simply the number of engines listed.
This guide compares the evidence a monitoring tool should provide, the operating models available, and the workflow we recommend for turning AI-answer visibility into decisions. Our multi-engine tracking signals explain why a raw answer, cited source, and competitive context matter more than an isolated percentage.
How Do Tools for Monitoring Brand Mentions Across AI Engines Work?
A reliable program starts with a fixed set of buyer questions, then runs those questions on a schedule across the answer engines your audience actually uses. It records the answer, the brands named, the wording around each brand, and any supporting links. That record is more useful than a screenshot because it gives your team something to inspect when visibility changes.
Engine coverage alone can mislead. AI Overviews and AI Mode can use different models and techniques, so the responses and supporting links can vary, as Google Search Central documents. That is why a monitoring program should capture answer mode, location, language, date, and model metadata when available, not just a single visibility score.
The core measurements should be explicit:
- Mention Rate: The share of tracked prompts that name your brand.
- Recommendation Rate: The share of answers that actively suggest your brand for the buyer's need.
- Citation Rate: The share of answers that cite one of your pages or domains.
- Competitive Share Of Voice: Your share of all tracked brand mentions within the defined competitor set.
- Narrative And Sentiment: The exact language, qualifiers, omissions, and tone surrounding the mention.
A strong prompt set combines category, comparison, alternative, problem-aware, and evaluation questions. We use buyer prompt research to keep those questions tied to how prospects evaluate a market, rather than how an internal team describes its product.
Manual testing can still help with a quick audit, but it breaks down when several engines, dozens of prompts, locales, and repeated runs are involved. The best tools preserve the prompt and response together, so a later change can be reviewed instead of guessed at.
Which Capabilities Make a Tool Comparable?
A monitoring tool becomes comparable when it makes its collection method and evidence accessible. A dashboard that says a brand was “visible” without showing the prompt, answer, source links, and calculation makes it difficult to explain the result to a content lead or executive.
Ask every provider the same questions. “Not publicly stated” is a legitimate procurement finding, especially for response retention, exports, alerts, API access, and security controls.
| Capability | What To Require | Why It Matters |
|---|---|---|
| Engine Coverage | Named engines and the exact answer mode monitored | A native answer, a web-enabled answer, and an AI search feature are different surfaces |
| Prompt Controls | Prompt import, editing, grouping, and version history | A changing prompt set can create a false trend |
| Repeat Frequency | Daily, weekly, or custom schedules | Cadence determines whether a drop is actionable |
| Full-Response Evidence | Retained response text with run metadata | Teams need to inspect the language behind every score |
| Citation Analysis | Cited URLs, domains, and source context | A cited page is not always a recommendation |
| Competitor Analysis | Defined peer set and share-of-voice method | Competitive visibility needs a consistent denominator |
| Localization | Country, language, and market controls | Buyer answers can differ by market |
| Reporting | Exports, scheduled reports, and client isolation | Evidence must travel beyond the dashboard |
| Governance | Access controls, retention, deletion, and audit terms | Sensitive prompts need a documented handling model |
ChatGPT Search may rewrite a query into targeted searches and can use general location information to improve relevance, according to OpenAI documentation. That makes location and search mode part of the evidence, not a setup detail.
For citation work, require both the source URL and the answer text that used it. Our citation tracking method helps distinguish an owned-page citation, an influential third-party source, and a competitor reference that requires review.
Native and Search-Enabled Answers
Do not collapse all answer experiences into one “AI engine” label. A search-enabled answer can retrieve current web sources and show citations, while a native answer may rely on model knowledge or a different retrieval process. Your tool should state which experience it checks.
Scores and Verbatim Evidence
A score is useful for trend reporting, but it cannot replace the underlying answer. Require a response view that lets your team confirm whether the brand was praised, merely listed, qualified heavily, or explicitly ruled out.
Prompts and Repeated Runs
Use a stable core prompt cohort for trends. Add exploratory prompts in a separate group, so new research does not accidentally look like performance improvement or decline.
How Should Teams Compare Monitoring Approaches?
There are several viable ways to monitor AI answers. The right model depends on whether your immediate need is a focused baseline, broad discovery, cross-engine reporting, or a program that connects findings to content and technical work.
| Monitoring Approach | Best Fit | Evidence To Confirm Before Buying | Typical Limitation |
|---|---|---|---|
| Manual Checks And Spreadsheet | Very early validation | Prompt log, answer copies, dates, and screenshots | Time-intensive and difficult to reproduce |
| Single-Engine Monitoring Tool | Teams focused on one priority answer surface | Prompt capacity, cadence, citation capture, and exports | Can miss where buyers receive different recommendations |
| Index-Led Discovery Platform | SEO teams researching broad category demand | Data source, refresh date, locale, and custom-prompt options | Indexed prompts may differ from your approved buyer panel |
| Cross-Engine Monitoring Platform | B2B teams with recurring competitive reporting needs | Full-response retention, engine modes, alerting, and client reporting | Requires deliberate prompt governance |
| PageLens.ai | Teams that need monitoring connected to practical action | Plan-level engine coverage, prompt volume, reporting scope, and governance needs | Advanced requirements should be scoped before commitment |
For PageLens.ai, our public Launch plan lists 100 tracked prompts checked weekly across ChatGPT, Google AI Mode, and Perplexity at $299 per month. Our higher plans list daily tracking and broader engine coverage, while Agency scope is designed for multiple client brands.
Perplexity describes its answers as grounded in real-time web sources with inline citations on its answer engine page. That is a useful reminder that cited-answer monitoring is not the same as tracking an ordinary search ranking.
Use cross-engine tracking to define which answer surfaces matter before you pay for every available engine. A startup selling to product-led SaaS buyers may need a narrower set than an agency supporting several international client categories.
What Does a Reliable Prompt Monitoring Workflow Include?
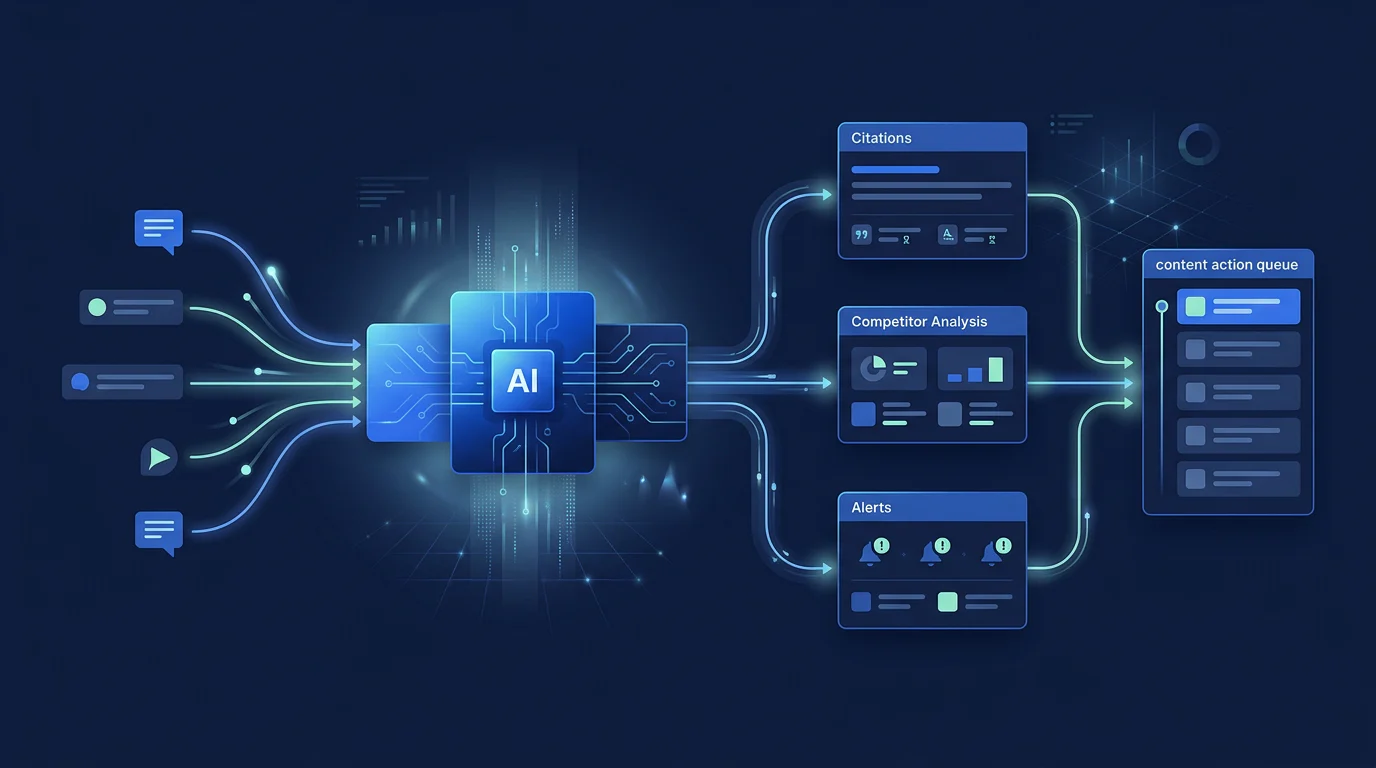
The most useful monitoring program is a decision system, not a recurring report. It begins with prompts that matter, records enough context to make results comparable, and gives a named owner a clear next action when an answer changes.
Google recommends using its generative AI performance reporting alongside broader measurement because its Search experiences remain rooted in core Search systems. Its official guidance supports treating that first-party traffic view as complementary to prompt-level monitoring, not a replacement for it.
Build a Controlled Prompt Panel
Start with 50 to 100 high-intent prompts, grouped by category, comparison, alternatives, pain point, and buying-stage questions. Keep the core group stable for reporting, and keep new tests separate until they have enough history to interpret.
A visibility audit is a practical first step when you do not know which prompts currently surface your brand, competitors, or influential cited pages.
Capture the Context with Every Run
Record the prompt, engine, answer mode, date, locale, language, model metadata when available, full response, cited URLs, named entities, and classification outcome. This makes a result reviewable months later and prevents a score from becoming a black box.
Review Recommendation Language, Not Only Mentions
A mention is not necessarily a recommendation. Inspect whether the answer positions your brand as a best fit, a niche option, an expensive option, a dated option, or an alternative it advises against.
Turn Evidence into a Governed Action
Assign every material change to a response: verify a source, improve a product page, update a comparison claim, publish an evidence-led resource, or continue observing. Our recommendation monitoring framework helps teams turn exact answer language into a controlled next step.
Why PageLens.ai Turns Monitoring into Action
At PageLens.ai, we built our workflow for teams that need more than a visibility score. We repeatedly run buyer-intent prompts across the engines included in your plan, preserve the answer evidence, identify citations and competitors, and connect findings to work your team can approve. Our public plans begin at $299 per month for 100 tracked prompts checked weekly across three engines, with broader daily coverage on higher tiers. We do not treat a missing mention as a verdict. We show the exact prompt, answer, cited sources, and framing so marketing, growth, SEO, and content leaders can decide whether to change a page, validate a competitor claim, or keep observing. If your program needs localization, reporting, client workspaces, or governance controls, we scope those requirements before you commit. Read how we work, then Book a demo
FAQs on Tools for Monitoring Brand Mentions Across AI Engines
The best choice depends on the prompts, answer engines, reporting needs, and governance requirements your team has already defined. These questions cover the practical requirements that most often determine whether a monitoring program remains useful after launch.
What Should a Multi-Engine Monitoring Tool Record?
It should record the exact prompt, engine, mode, locale, run date, full answer, cited URLs, named brands, classification logic, and a comparable trend over time.
How Often Should Teams Run Buyer Prompts?
Run a stable core daily for fast-moving categories, use weekly checks for lower-priority prompts, and repeat important prompts enough to identify answer variation with confidence.
Can I Measure Sentiment in AI Answers?
Yes, but inspect retained answers alongside scores. A positive label can hide qualifications, omissions, outdated details, or wording that makes your brand a weak recommendation.
How Should I Compare Monitoring Tool Prices?
Compare monthly price with prompt allowance, engines, scheduled runs, retained answers, exports, seats, locations, and onboarding. Low starting prices may support less evidence each month.
What Security Questions Should Enterprises Ask?
Request security documentation, data-processing terms, retention and deletion policy, access controls, audit logs, export rules, incident process, and required single sign-on commitments in writing before purchase.