B2B Buyer Prompt Research with PageLens.ai: How to Find What Buyers Ask AI
TL;DR
B2B buyer prompt research: find, label, score, and validate the questions buyers ask AI without confusing simulations for real demand.
B2B Buyer Prompt Research with PageLens.ai: How to Find What Buyers Ask AI
A 2026 Gartner survey found that 45% of B2B buyers used generative AI to gather vendor and product information. That makes buyer language research a practical revenue question, not an abstract SEO exercise.
You cannot see private prompts entered into public AI assistants unless a user shares them or a provider supplies an appropriately aggregated dataset. B2B Buyer Prompt Research works by combining consented buyer language, owned-site conversations, public evidence, demand proxies, and controlled simulations, then labeling each record by source, confidence, intent, audience, and buying stage.
We will show how to collect the evidence, avoid privacy and attribution mistakes, turn it into a usable prompt library, and validate whether better answers improve your AI visibility.
How Do You Collect Observed Buyer Language?
The highest-confidence prompt evidence is language buyers actually used in a conversation with us. Sales calls, support tickets, win-loss notes, onboarding questions, and demo-form responses reveal the constraints buyers attach to a category: budget, team size, implementation effort, integrations, risk, timing, and approval requirements.
This is the foundation of buyer prompt discovery. It does not prove someone typed the same sentence into an assistant, but it gives us real wording from people evaluating or using the category. That is more useful than pretending a simulated phrase is observed demand.
Preserve the Verbatim Record
Capture the original wording before normalizing it into a cleaner research phrase. “Can this fit our approval process?” and “Do you support multi-step approvals?” may represent one theme, but the first record carries the uncertainty and buyer context that the second loses.
Use a narrow, governed record:
- Verbatim language: The buyer’s original question or objection, redacted where needed.
- Source type: Sales call, support request, win-loss note, onsite search, or another approved source.
- Decision context: Role, segment, product area, buying stage, and date range.
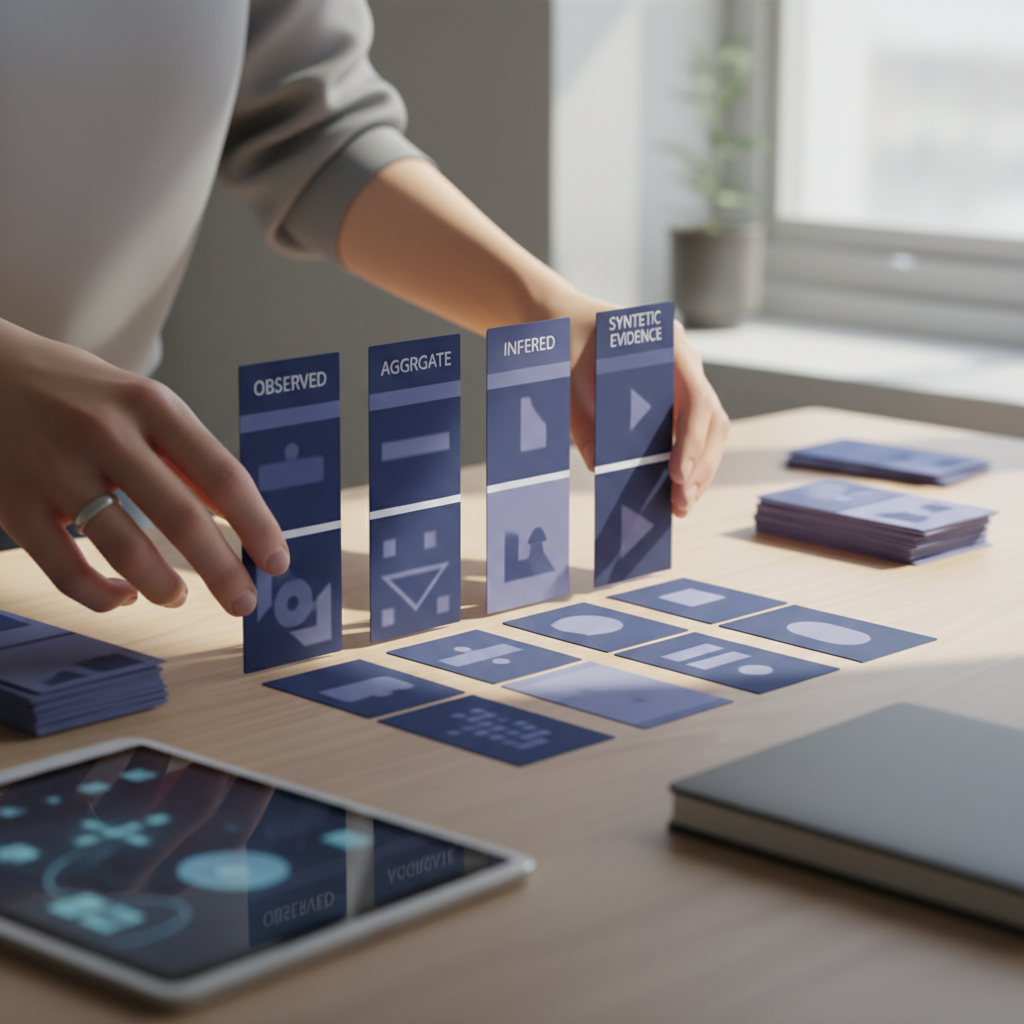
- Evidence label: Observed, aggregated, inferred, or synthetic.
- Validation status: Unreviewed, corroborated, contradicted, or ready for action.
Pseudonymization reduces linkability but does not automatically turn personal information into non-personal information. Follow relevant privacy guidance and keep raw transcripts separate from the reduced dataset used for content research.
Run a Five-Step Collection Cycle
A repeatable collection cycle keeps a useful library from becoming a list of memorable anecdotes.
- Confirm which systems, recordings, and notes are approved for research use.
- Export only question-bearing excerpts and remove names, contact details, and sensitive account context.
- Add source, date, role, segment, and buying-stage fields while preserving the original wording.
- Group near-duplicates without deleting meaningful variations in phrasing or constraints.
- Ask sales and support to review the strongest clusters on a regular cadence.
Map Language to Buyer Decisions
Do not sort questions by opening words alone. “How do I,” “what happens if,” and “is this better than” can occur at any stage. Sort by the decision a buyer is trying to make: understand a problem, assess fit, compare options, resolve risk, or commit.
That distinction helps us build content around the buyer’s actual job rather than force every question into a generic funnel label.
How Do You Compare Onsite, Public, and Aggregated Sources?
Observed first-party language is not the only useful source. Onsite search, chatbot conversations, public community discussions, and category-level datasets each add coverage, but they answer different questions and require different confidence levels.
A search query on our site may show immediate intent. A public discussion can reveal vocabulary and objections. An aggregated dataset may surface recurring patterns across a category. None should be reported as direct access to a person’s private assistant history.
| Source | Evidence Status | Strength | Main Limitation |
|---|---|---|---|
| Consented sales and support language | Observed | Verbatim buyer context and commercial relevance | Limited to known prospects and customers |
| Onsite search and chatbot logs | Observed | Captures self-directed research on owned properties | Does not show private assistant behavior |
| Public communities and reviews | Observed public language | Reveals objections, sentiment, and phrasing | Does not establish category-wide frequency |
| Category-level prompt datasets | Aggregated | Can identify reported themes, intent, and entities | Collection and coverage may be opaque |
| Search-query data | Inferred | Shows demand wording and modifiers | Search terms are not AI-chat prompts |
| AI-answer monitoring | Observed output | Reveals response, citation, and accuracy gaps | Does not prove buyer demand |
| Controlled simulations | Synthetic | Creates testable hypotheses quickly | Must never be presented as observed demand |
Use prompt research versus keyword research to keep those distinctions operational. Search data is valuable, but it is a proxy. A buyer can type a two-word query into a search engine and then ask an assistant a detailed question with constraints that never appeared in the keyword.
For conversational data, minimize the fields we store, document the purpose, restrict access, and establish deletion or review dates. NIST guidance emphasizes evaluating disclosure risk and selecting an appropriate sharing model rather than assuming that simple masking is sufficient.
Public language deserves the same restraint. We can extract a category theme from a discussion without reproducing identifiable details, treating one person’s experience as market truth, or claiming their question was asked inside an AI assistant.
How Do You Turn Search and AI Responses into Evidence?
Search data helps us identify recurring category language, while AI-answer monitoring shows how assistants currently frame the category. Together, they help us distinguish a demand signal from an answer-quality gap.
The key is to test stable prompts repeatedly, record the result, and treat an assistant’s answer as observed output rather than evidence that a buyer asked that exact prompt. That makes citation tracking useful for validation, not a substitute for buyer research.
Build a versioned test set from high-confidence records. Every test should retain the prompt wording, engine, date, response summary, cited sources, mention status, accuracy status, and reviewer notes. If a response changes, we can identify whether the prompt, timing, cited material, or product facts changed too.
Provider policies reinforce why an outside research workflow should not claim access to private chats. The OpenAI policy distinguishes consumer controls from business products, whose inputs and outputs are not used for training by default. The responsible conclusion is simple: monitor public outputs and approved data, never imply hidden-message visibility.
A useful review cycle asks four questions:
- Did the answer mention our category, product type, or relevant differentiator?
- Were the facts accurate, current, and properly qualified?
- Which pages or third-party sources shaped the answer?
- Did sales feedback or conversion behavior support the cluster’s importance?
For a broader measurement model, connect this workflow to multi-engine AI tracking. Mention rate matters, but accuracy, citations, and downstream buyer feedback determine whether a visibility gain is valuable.
How Do You Use Simulations Without Mistaking Them for Demand?
Simulations are excellent for hypothesis generation. They are not a replacement for buyer evidence. We use them to identify likely follow-up questions, decision criteria, comparison angles, and missing documentation that observed sources can later confirm or reject.
Start with a real cluster, such as integration uncertainty or security review friction. Then ask an assistant to produce possible decision questions for that specific scenario. Record the model, date, seed evidence, and output as synthetic. If the same theme later appears in sales calls, support logs, onsite search, or an appropriately aggregated source, upgrade the confidence based on that corroboration.
A good simulation workflow stays grounded:
- Seed evidence: Begin with an observed or aggregated cluster, not an invented persona.
- Controlled context: Use a clean session and avoid personal, customer, or confidential information.
- Hypothesis output: Ask for plausible follow-ups, tradeoffs, and criteria rather than “real prompts.”
- Synthetic label: Mark every generated item clearly and permanently.
- Validation task: Assign a concrete check against first-party or aggregated evidence.
We can also use simulations to inspect answer language and sentiment, but the interpretation should remain transparent. Our sentiment tracking architecture approach helps separate what an assistant said from what buyers themselves have actually said.
Do not add special schema in the hope that it makes synthetic research more credible. Google’s AI feature guidance says there is no special structured data required for AI features. Clear, helpful, crawlable content and accurate evidence still do the work.
How Do You Score and Validate B2B Buyer Prompt Research?
A prompt library becomes useful when it directs a content, product-marketing, or sales action. We score clusters, not isolated sentences, because buyers phrase the same underlying concern differently across roles and stages.
Apply a five-part rubric, scoring each criterion from zero to five. The maximum is 25 points, but the score should never override evidence labeling. A synthetic cluster may be highly answerable, for example, while still requiring validation before it earns roadmap priority.
| Criterion | Score 0 | Score 5 |
|---|---|---|
| Evidence Strength | One unsupported synthetic or inferred record | Multiple corroborated observed records |
| Commercial Intent | General curiosity | Clear evaluation, comparison, objection, or decision signal |
| Frequency | Isolated occurrence | Repeated across relevant approved sources |
| Category Relevance | Peripheral topic | Directly affects category selection or adoption |
| Answerability | No credible asset can answer it | We can publish a clear, evidence-backed answer |
Apply a Clear Labeling Convention
Use O for observed language, A for reported aggregated patterns, I for inferred signals such as search data, and S for synthetic hypotheses. A cluster can contain several labels, but it should never be described using only its strongest label if weaker evidence is doing the real work.
This makes AI visibility tracking more accountable. We can explain why a prompt entered the roadmap, what it represents, and what evidence would change the decision.
Cluster Prompts by Funnel Stage
Cluster by the decision a buyer needs to make, then map that cluster to an answer format.
| Stage | Buyer Need | Best Content Response |
|---|---|---|
| Awareness | Define a problem or option | Explainer, glossary, use-case guide |
| Consideration | Assess requirements and workflow fit | Buyer guide, implementation overview |
| Comparison | Evaluate alternatives and tradeoffs | Comparison table, decision framework |
| Objection | Resolve risk, effort, security, or cost concern | Detailed FAQ, proof, limitations |
| Decision | Gain confidence to proceed | Checklist, documentation, next-step page |
The goal is not to create one page per prompt. We use a cluster to build a complete answer that anticipates reasonable follow-ups while staying accurate about product capabilities. This is especially useful for smaller product sites, where each page needs a defined job in the wider content system.
Close the Validation Loop
The loop is straightforward: prompt library, repeated answer tests, citation and accuracy review, content update, conversion signal, sales feedback, then rescoring. Keep a record of each change so we can learn whether visibility shifted because the answer improved, the evidence changed, or the category itself moved.
When publishing FAQs, use structured data only when it matches visible content. Google’s FAQ guidance limits FAQ rich-result treatment largely to authoritative government and health sites, so markup is not a shortcut to citation.
Put B2B Buyer Prompt Research into Practice with PageLens.ai
We help teams turn a scattered set of answer-engine observations into a governed research loop. We use the same discipline described here: preserve source labels, test a stable prompt set, inspect citations and answer accuracy, then connect the findings to content and sales feedback. That means teams can discuss what is observed, inferred, or simulated without letting a dashboard blur the difference. Start with one category, one ICP, and a manageable prompt library. Bring in sales, support, content, and product marketing only where each can validate evidence or act on it. We can then help you monitor the question clusters that matter, prioritize response gaps, and keep a record of why each content decision was made with clear ownership, repeatable reviews, and useful evidence for each decision. If you want to see how the workflow can fit your operating rhythm, Book a demo with our team at PageLens.ai.
FAQs on B2B Buyer Prompt Research
Can a Tool See Private AI Chat Prompts?
No. Outside tools cannot inspect private assistant conversations. Use consented buyer language or aggregated datasets, and label simulations and search proxies clearly in research reporting.
What Is the Most Reliable Prompt Source?
Consented sales and support conversations are strongest because they preserve actual buyer language and commercial context. They still need anonymization, access controls, retention limits, and review.
Are Search Keywords the Same as AI Chat Prompts?
No. Search terms are inferred signals, while chat prompts often include context, constraints, and follow-up questions. Store search data separately and retain its inferred label.
How Should We Use Synthetic Prompts?
Use simulations to generate hypotheses about criteria, comparisons, and objections. Record model and date, label results synthetic, then check them against observed evidence before prioritizing content.
How Often Should We Validate a Prompt Library?
Review priority clusters regularly and after material product, market, or messaging changes. Repeat assistant tests, inspect citation accuracy, and use sales feedback before reprioritizing content priorities.