
How to Automate AI Brand Visibility Tracking with PageLens.ai
Automate AI brand visibility tracking with controlled prompt runs, evidence capture, dashboards, alerts, and action workflows.
How to Automate AI Brand Visibility Tracking with PageLens.ai
AI answer monitoring has practical infrastructure limits: Google documents a cap of one million queries per day for Grounding with Google Search, even though most brand programs need far less volume.
Automated AI brand visibility tracking repeatedly runs a controlled library of buyer prompts, stores each engine’s full response, and measures mentions, citations, sentiment, competitors, and share of voice over time. It goes beyond keyword tracking because each observation preserves the prompt, engine, model or mode, market, timestamp, response, and cited sources.
This guide explains how to build the prompt library, capture defensible evidence, automate repeat runs, interpret the dashboard, and turn findings into content and reputation actions.
How Does Automated AI Brand Visibility Tracking Work?
A keyword rank tracker asks where one page appeared for one query. An AI visibility system asks what an answer engine said when a buyer asked a defined question. The answer may name several brands, cite unrelated sources, make a recommendation without a link, or change wording on the next run.
That difference changes the data model. We treat every prompt response as an observation with a known configuration, rather than treating a single answer as a permanent ranking. This creates an evidence trail your marketing, SEO, content, and leadership teams can inspect when a dashboard moves.
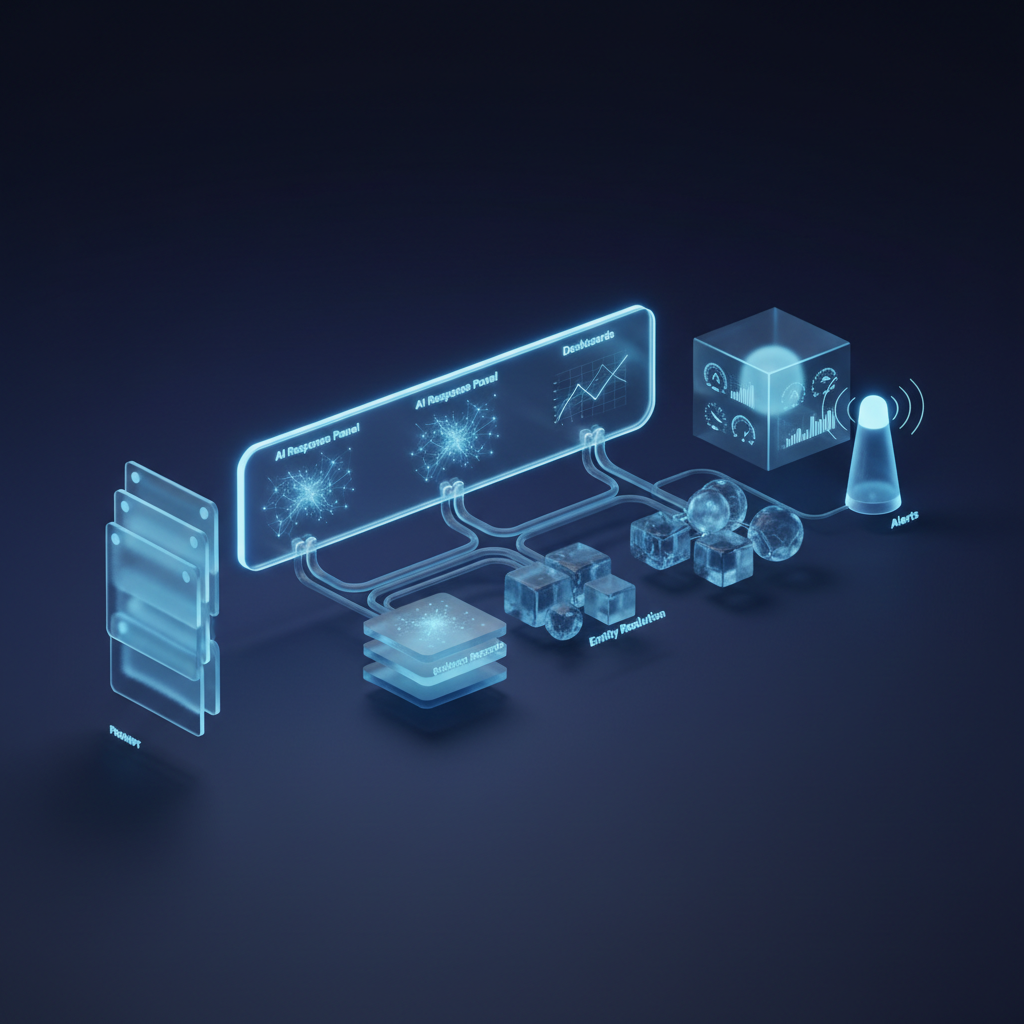
The workflow is straightforward: define buyer prompts, run them in controlled environments, retain the complete answer and sources, resolve entities, calculate metrics, then route meaningful changes to a responsible person. Our guide to AI visibility tracking explains why this is a measurement discipline, not a replacement for traditional SEO reporting.
A mention is an entity-level event: an answer names your brand, product, or approved alias. A citation is an evidence-level event: an engine exposes a source URL supporting part of its answer. They can happen together or separately, so neither should be treated as a proxy for traffic, conversion, or buyer preference.
| Metric | Definition | Useful Question |
|---|---|---|
| Mention | Your brand, product, or approved alias appears in answer text | Are we present in relevant answers? |
| Recommendation | The answer positions the brand as a suitable option | Are we being presented as a choice? |
| Citation | The engine exposes a source URL or linked evidence | Is a source visible for this answer? |
| Visibility Rate | Qualifying mention runs divided by eligible runs | How often do we appear? |
| Share Of Voice | Your tracked-brand mentions divided by all tracked-brand mentions | How visible are we relative to the set? |
| Sentiment | Coded language about the brand with exact supporting text retained | How does the engine describe us? |
| Cited-Source Ownership | Citations from verified brand domains divided by captured citations | Are our own sources being surfaced? |
How Do AI Answer Engines Behave Differently?
No engine should be treated as a generic “AI search” bucket. Citation interfaces, search behavior, and user settings differ, which is why an enterprise dashboard should show results by engine before showing an aggregate view.
ChatGPT Search may rewrite a user question into more targeted searches, and it can use location to improve relevance. Its answers may show inline citations or a Sources panel, so the run record should capture whether Search was active and which response experience was observed. OpenAI documentation also makes clear that site inclusion does not guarantee placement.
| Engine | Citation Behavior | Link Availability | Monitoring Limitation |
|---|---|---|---|
| ChatGPT Search | May display inline citations or a Sources panel | Conditional on the response experience | Search state, query rewriting, and location can affect results |
| Perplexity | Provides citations and source links in its answer experience | Expected when citations are shown | Referral data cannot reveal uncaptured mentions |
| Claude With Web Search | Provides direct citations when web search is used | Available in web-search responses | Search settings, availability, and location can vary |
| Gemini With Google Search Grounding | Can return URL citation annotations and search metadata | Available in grounded API output | API output is not automatically identical to consumer interfaces |
Perplexity describes its answers as including citations and links to original sources, while Claude’s web-search experience provides direct citations when that feature is active. Claude’s web-search guide is a useful reminder to log the enabled mode, not just the engine name.
For Gemini, grounded API responses can include search queries, source URLs, and citation annotations tied to parts of the generated text. That makes source capture especially valuable, but it also means teams must document the exact model and grounding configuration. Use multi-engine signals to compare behavior without flattening unlike evidence into one score.
How Do You Build and Run a Prompt Library?
A useful prompt library reflects how buyers actually frame a problem, shortlist options, compare alternatives, and validate a decision. It is not a long list of keywords rewritten as questions. We start with intent, persona, market, and commercial importance, then make each prompt stable enough to run repeatedly.
Define a Six-Intent Prompt Taxonomy
Use awareness prompts for category education, consideration prompts for shortlist research, decision prompts for pricing or implementation questions, comparison prompts for alternatives, problem prompts for pain points, and brand prompts for direct reputation checks.
Each record should include a prompt ID, version, buyer role, target market, intent, priority, and whether the prompt names your brand. Brand-named prompts are valuable for monitoring misinformation, but they should not inflate category visibility. Our approach to buyer prompt discovery helps teams turn actual buyer language into a durable measurement set.
Build a Manual Baseline First
Before automation, run a fixed starter set across the engines that matter to your buyers. Record the full answers, sources, named brands, recommendation language, and the settings used. This provides calibration material for reviewers and exposes ambiguity in your entity dictionary.
A practical first pass might use 24 prompts, four engines, and three repeats, producing 288 observations. That is a starting configuration for learning, not a universal statistical threshold. The right volume depends on your category, markets, decision cycle, and the consistency of the engine experience.
Schedule Repeat Runs by Priority
Run high-priority brand and decision prompts more often than broad category questions. A stable schedule accumulates evidence, while an event-driven run can investigate a product launch, messaging change, or reputation issue. Keep scheduled and ad hoc runs separate in reporting.
The monitored unit is a prompt run, not a position. The output should retain the exact text received, even if later automation classifies it differently. For a deeper comparison of input design, see prompt research.
Assign Owners Before Alerts Fire
Marketing and SEO should own prompt coverage and action priorities. Analytics should own run health, denominators, and dashboard definitions. Content, communications, and product teams should own the actions triggered by verified evidence.
This ownership model prevents the familiar failure mode where a dashboard identifies a gap but no team is responsible for resolving it.
What Data Pipeline Makes Results Trustworthy?
Automation is only credible when a team can trace a score back to the prompt and answer that created it. We preserve raw evidence first, then add normalized fields and quality checks. That sequence protects the record when a model changes, an extractor is updated, or a reviewer disagrees with a classification.
Google’s grounded response documentation shows why source-level evidence matters: the output can include URLs, titles, search queries, and citations attached to text spans. Gemini grounding documentation supports capturing this metadata instead of reducing every response to a yes-or-no mention flag.
Preserve the Full Observation
Each observation should retain the prompt, prompt version, engine, model or mode when visible, market, locale, timestamp, full response, source URLs, extraction result, and review status. Also record failures such as unavailable search, blocks, timeouts, and changed interfaces.
A clean session is usually preferable for a controlled run. Where settings allow it, document whether memory, personalization, custom instructions, location, or prior conversation context could affect the answer.
Normalize Entities and Sources
Maintain an approved dictionary of brand names, product names, abbreviations, common misspellings, and excluded same-name entities. Resolve a cited URL to a canonical domain before calculating cited-source ownership, including redirects and approved subdomains.
Do not let automated sentiment overwrite the answer itself. Store the exact sentence or passage supporting the label, the classifier version, and a confidence score. Our sentiment architecture explains why language evidence and dashboard labels must remain connected.
Quality-Check Automated Classifications
Review a fixed sample of new classifications every week, especially when models, source formats, or extraction logic change. Report disagreement rates, unresolved aliases, and failed runs alongside visibility metrics so the dashboard shows uncertainty instead of hiding it.
NIST recommends systematic documentation and regular assessment of metrics and controls in AI monitoring programs. NIST monitoring guidance provides a sound operating principle: measure the system you have, document the conditions, and reassess controls as conditions change.
How Do You Interpret Results and Turn Them into Action?
Visibility rate is simple: qualifying mention runs divided by eligible runs. Share of voice is a separate calculation: your tracked-brand mentions divided by all tracked-brand mentions in the same engine, prompt set, market, and period. Keeping the denominators visible prevents false comparisons.
A weekly dashboard should separate engines, intents, markets, and prompt versions. It should also expose execution failures and zero-result states. If a visibility decline appears, first inspect run health, setting changes, model or mode changes, and sample size before changing content strategy.
Build a Weekly Review Checklist
- Confirm The Denominator: Check whether prompts, engines, markets, or repeat counts changed.
- Inspect Evidence: Open representative answers and sources behind major gains or losses.
- Separate Signal Types: Review mentions, recommendations, citations, sentiment, and cited-source ownership independently.
- Check Run Health: Keep blocked, failed, and unavailable runs visible.
- Assign The Next Step: Give every verified issue an owner and due date.
Use an Action Matrix Instead of a Generic Alert
| Signal | First Diagnostic | Action |
|---|---|---|
| Zero Mentions | Review the prompt, intent, answer evidence, and other brands named | Prioritize the relevant evidence or content gap |
| Mentions Without Citations | Inspect cited sources and verified-domain coverage | Strengthen source eligibility and supporting evidence |
| Negative Language | Preserve the exact statement and sources | Verify the claim, then route to product or communications |
| Declining Visibility | Validate controls, run health, and trend window | Re-run a controlled sample before changing strategy |
A zero mention is not automatically a content brief. It may indicate a narrow prompt, a market-specific gap, an entity-resolution issue, or a change in the answer experience. The best response starts with the evidence, then moves to a prioritized action. Use content optimization when a verified visibility gap needs a specific page or evidence plan.
Calculate Return on the Monitoring Workflow
Calculate manual labor cost as manual hours multiplied by loaded hourly cost. Calculate net benefit as hours saved multiplied by loaded hourly cost, minus tool cost. Then divide net benefit by tool cost to calculate ROI.
For example, a team spending 15 hours each week on manual checks is using 780 hours annually before counting reporting and review. The actual business case depends on the team’s loaded hourly cost, the time automation saves, and the quality of the decisions the monitoring system enables.
How PageLens.ai Helps Teams Operationalize Tracking
We give marketing, growth, SEO, and content leaders a way to turn scattered checks into an operating rhythm. We help teams organize buyer prompts, preserve response evidence, compare engines without flattening their differences, and route meaningful movement to the people who can act on it. Our approach keeps the raw answer beside the score, so a leadership dashboard never asks readers to trust a number they cannot inspect.
We can begin with the prompt library your team already uses, define the markets and sources that matter, and establish a baseline before automating. From there, our workflows support recurring measurement, reviewable evidence, and priorities that connect visibility gaps to content, reputation, and product work. You retain ownership of the strategy and the evidence, we make the monitoring system easier to operate. Our team can help you scope the first cycle. Explore the PageLens.ai platform and Book a demo
FAQs on Automated AI Brand Visibility Tracking
These answers clarify the operating rules that keep automated monitoring useful for marketing, SEO, growth, and content teams.
How Often Should Teams Run AI Answer Monitoring?
Run high-priority brand and decision prompts daily, broader category prompts weekly, and review trends monthly. Increase repeats before acting on a surprising individual response.
What Is the Difference Between a Mention and a Citation?
A mention names a brand in answer text. A citation exposes a source URL. Either can occur alone, so report them separately with supporting response evidence.
Can Analytics Track Every AI Brand Mention?
Not completely. Analytics can record referral sessions when a user follows an exposed link, but it cannot count unclicked citations or brand mentions inside an answer.
What Must Every Observation Retain?
Keep the prompt and version, engine, model or mode when visible, market, timestamp, full response, cited sources, extraction result, and quality-review status so analysts can reproduce and interpret changes.
How Is Visibility Rate Calculated?
Divide qualifying mention runs by eligible runs for visibility rate. Calculate share of voice from tracked-brand mentions in the same engine, prompt set, and period.