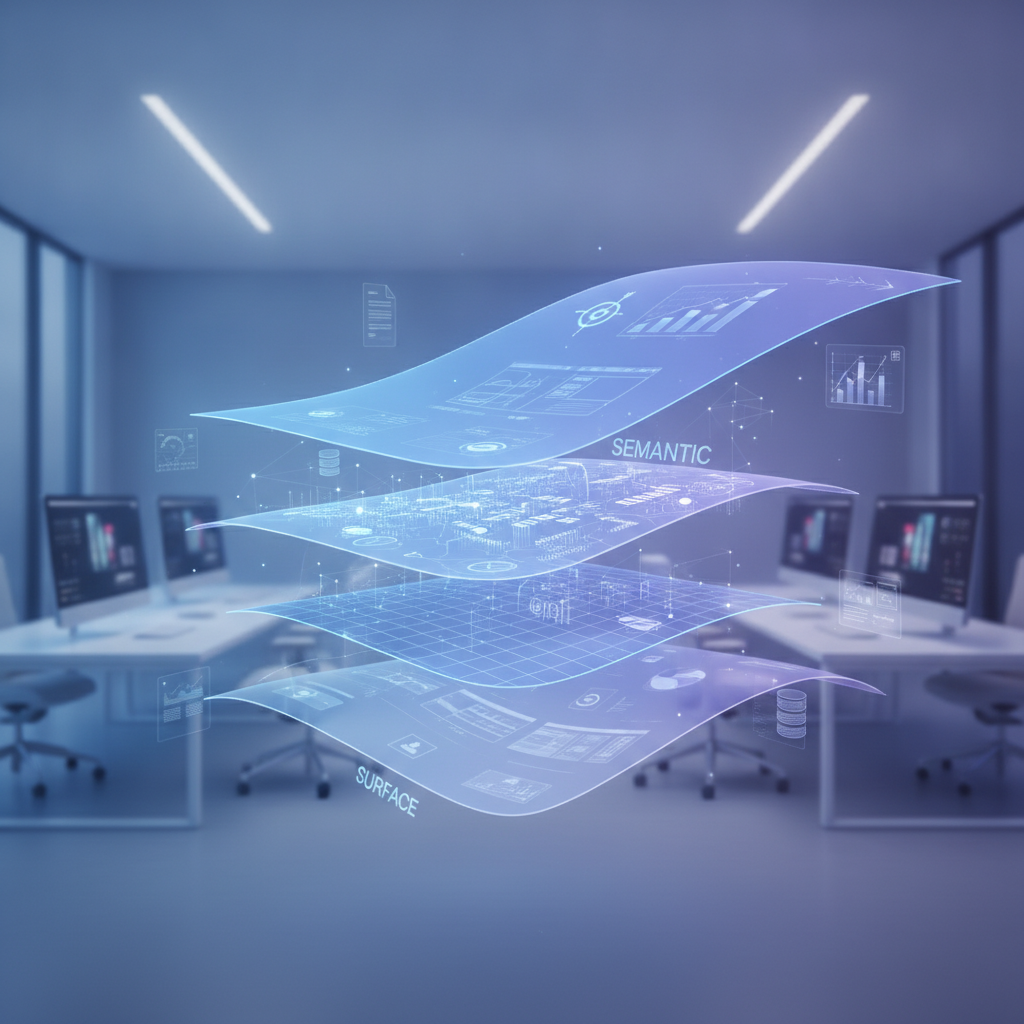
TL;DR
Use a four-tier content optimization stack to turn AI visibility monitoring into measurable surface, structural, semantic, and strategic improvements.
Beyond Monitoring: The 4-Tier Content Optimization Stack
AI answer features now make source selection a content problem as much as a monitoring problem. In March 2025, Google said AI Overviews were used by more than one billion people.
Content optimization beyond monitoring means choosing the smallest change that solves the observed AI visibility problem: surface fixes for legibility, structural rewrites for answerability, semantic connections for evidence context, and strategic expansion for missing buyer prompts. Measure each tier against a fixed prompt set before moving to a deeper intervention.
This guide turns content optimization beyond monitoring into a practical system for choosing the next fix, measuring lift, and avoiding busywork that does not improve source usefulness.
Why Content Optimization Beyond Monitoring Needs Tiers
Most teams respond to a weak citation rate with a larger dashboard, a longer list of prompts, or a generic rewrite. That mixes four distinct failure modes. Content optimization beyond monitoring separates them, so the team can fix the page’s real constraint, record the intervention, and avoid needless rewrites.
Use the tier that matches the failure, then retest.
In practice, content optimization beyond monitoring gives every test a named purpose instead of treating every weak result as a request for more content.
A page can be discoverable without being cited, cited without materially shaping an answer, or well structured but missing the buyer prompt entirely. Research across 602 controlled prompts found that citation selection and answer-level influence are different outcomes, which is why citation absorption research matters for planning.
| Tier | Main Question | Typical Fix | What To Measure |
|---|---|---|---|
| Surface | Can systems access and identify the page? | Crawlability, metadata, markup, visible text | Eligibility and indexing checks |
| Structural | Can the page answer the question clearly? | Answer blocks, claims, tables, steps | Page-level citation rate |
| Semantic | Does the page connect claims to useful context? | Entity coverage, sources, internal links | Evidence and topic coverage |
| Strategic | Does the site serve the full buyer prompt set? | New pages, prompt clusters, content hubs | Coverage by intent and engine |
That is why content optimization beyond monitoring should begin with diagnosis, not a blanket instruction to “make the content more AI-friendly.” Start with the signals to track, then match each signal to a specific content decision.
Tier 1: Surface Fixes Make the Page Legible
Surface work is the entry tier for pages that bots or readers cannot reliably identify, access, or classify. It covers crawlability, visible source text, informative titles, useful descriptions, and accurate markup. This is content optimization beyond monitoring at its least invasive, but it still needs a measured outcome.
First, make the page understandable before making it more elaborate.
At this stage, content optimization beyond monitoring is a clarity exercise: identify the page, its evidence, and the path that leads readers to it.
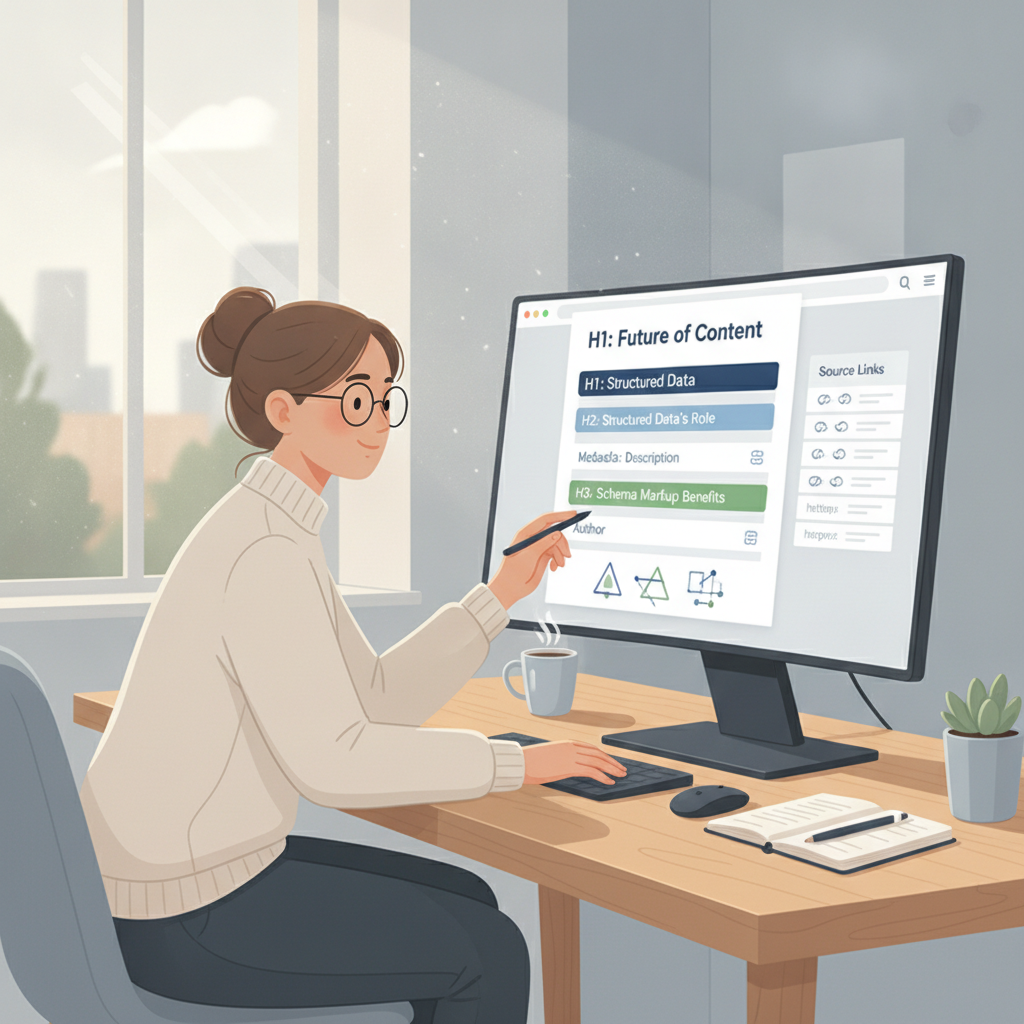
Use a clear H1, a unique title, an accurate meta description, crawlable internal links, and key facts in page text rather than image-only graphics. Google explains that structured data can help systems understand page content, while its testing guidance also makes clear that valid markup does not guarantee a special appearance.
The practical test is simple: can a reader, a crawler, and an AI retrieval system identify what the page answers, who created it, and where its supporting evidence lives? If not, structural rewriting is premature. A consistent single-site citation workflow gives teams a baseline before they change titles, links, or markup.
A useful surface fix might replace a generic “Complete Guide” title with a specific problem statement, expose an overlooked source link in the body, and connect the page from a relevant hub. That discipline keeps content optimization beyond monitoring focused on clarity rather than cosmetic edits.
Tier 2: Structural Rewrites Make Evidence Extractable
Structural work is for pages that can be found but fail to provide a crisp, supportable answer. The goal is not to shorten every article. It is to organize claims, evidence, comparisons, and steps so a person or system can understand what each section contributes.
Next, make the answer easier to extract and verify.
Here, content optimization beyond monitoring focuses on answerability: readers should be able to identify the claim, evidence, limitation, and next action without searching through the page.
A strong structural rewrite puts the direct answer near the relevant question, then follows it with evidence, limitations, and next actions. It uses descriptive headings, short claim paragraphs, comparison tables where readers must choose, and numbered steps where readers must act. A six-engine preprint reported a 17.3% citation-rate improvement from structural feature work, but that structural study is directional evidence, not a guaranteed result for any page.
| Weak Structure | Stronger Structure | Why It Helps |
|---|---|---|
| Long feature narrative | Direct answer followed by evidence | Makes the page’s claim explicit |
| Unlabeled list | Comparison table with decision criteria | Makes tradeoffs easier to inspect |
| Repeated definitions | One canonical definition with links | Reduces ambiguity |
| Broad conclusion | Specific next step and limitation | Gives the answer usable boundaries |
Content optimization beyond monitoring at this tier means improving answerability without adding empty detail. It also avoids the common mistake of turning every page into a question-and-answer template. Structure should fit the user job, whether that job is comparison, implementation, diagnosis, or evaluation.
For a broader view of how page architecture and meaning work together, see AEO and semantic SEO. This is why content optimization beyond monitoring preserves useful nuance while making evidence easier to locate.
Tier 3: Semantic Optimization Connects the Evidence
Semantic work addresses pages that contain good information but lack the relationships that make it useful in a wider topic system. It connects named concepts, primary evidence, related pages, and clear terminology, so each claim sits in a context that readers can explore and validate.
Then, connect the page to the rest of the evidence.
In this tier, content optimization beyond monitoring turns related facts into a usable topic system rather than leaving each page to stand alone.
Start with entities that matter to the buyer’s decision: the problem category, method, metric, constraint, and implementation term. Define each once, use the same language consistently, and link to the page that explains it in depth. Google recommends descriptive internal anchor text because it helps people and systems understand linked pages, as explained in its link best practices.
Semantic optimization also means citing primary or authoritative sources directly after material factual claims. A reader should not need to hunt through a page to discover where a statistic came from or what a recommendation assumes. The result is content optimization beyond monitoring with clearer evidence boundaries and fewer unsupported additions.
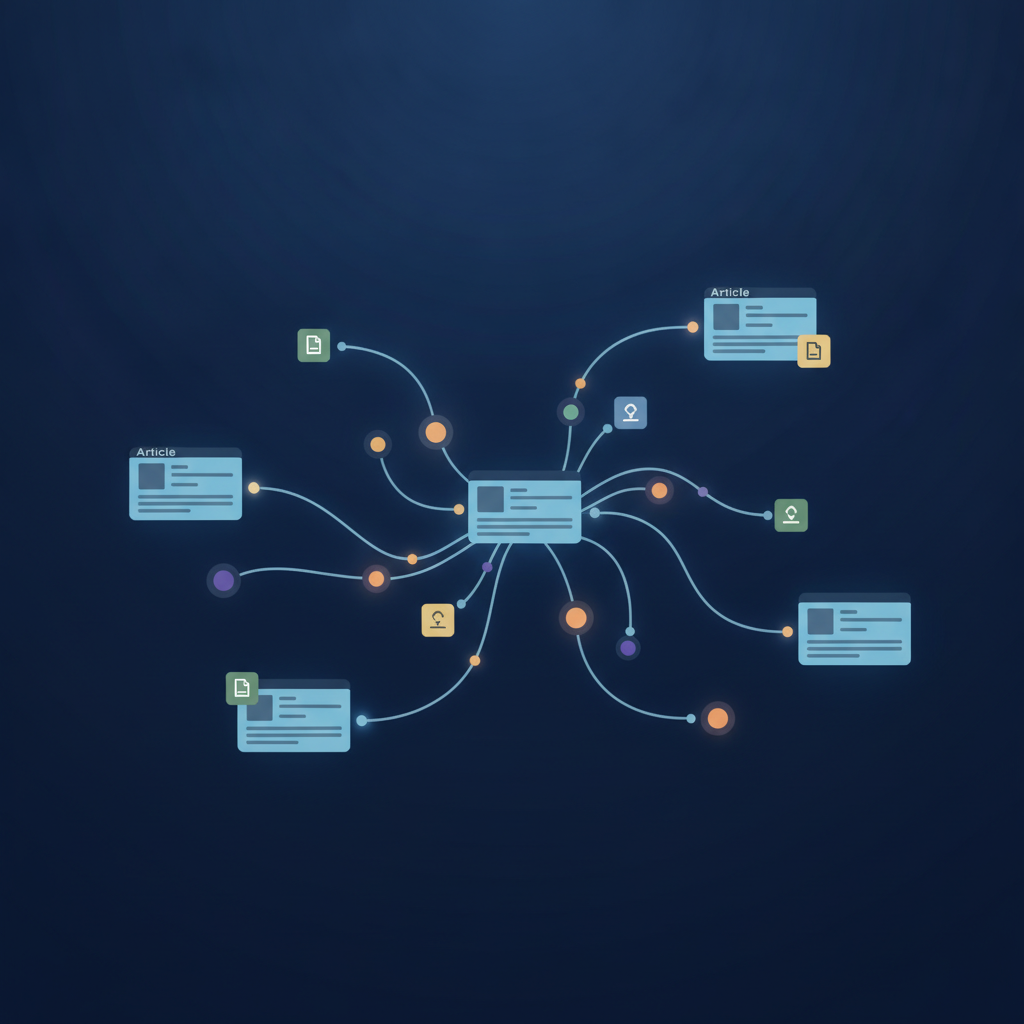
Use internal links as topic connections, not decorative navigation. For example, a measurement guide should lead naturally to prompt research vs keyword research, while a strategy page should point readers to the operational page that explains execution. The goal is a coherent evidence graph, not a higher raw link count.
Tier 4: Strategic Optimization Expands Buyer Coverage
Strategic work is for sites whose individual pages are sound but whose content portfolio misses important buyer questions. The problem is no longer a single URL. It is an incomplete prompt set, a thin comparison path, or a lack of useful content for a decision stage.
Finally, create coverage where no existing page can credibly answer.
For this reason, content optimization beyond monitoring has a portfolio dimension: the site must answer the right questions, not merely improve the pages it already has.
Build a prompt inventory from the questions buyers ask before, during, and after evaluation. Group prompts by intent, then map each group to an existing page, a page needing expansion, or a genuinely new resource. Content optimization beyond monitoring reveals whether the gap is a weak page, an unclear page purpose, or missing coverage altogether.
Do not force one broad guide to answer every question. A buyer comparing approaches needs criteria and tradeoffs. A practitioner needs implementation steps. A leader measuring progress needs definitions and denominators. OpenAI notes that web search can rewrite requests into more targeted queries, which makes search behavior guidance a useful reminder that literal keyword matching is not the whole task.
Use buyer prompt discovery to separate missing topics from weak pages. Strategic expansion should add unique evidence or a new decision path, not create near-duplicate articles around small wording variations.
Choose the Right Tier with a Decision Tree
A tiered model works only when teams can choose a next step without turning every low-performing page into a full rewrite. The decision should begin with accessibility and evidence, then move toward page structure and portfolio coverage only when the earlier layers are sound.
Use this sequence to keep intervention proportional.
A decision tree keeps content optimization beyond monitoring proportional, so a minor surface issue does not become an unnecessary sitewide rewrite.
- Can the target page be crawled, accessed, and accurately described?
- Does the page give a direct answer supported by specific evidence?
- Are key concepts, sources, and related pages connected in context?
- Does the site have a dedicated page for the buyer prompt being tested?
If the first answer is no, use Tier 1. If the page is accessible but vague, use Tier 2. If it is useful but isolated, use Tier 3. If it cannot serve the prompt without becoming unfocused, use Tier 4. Content optimization beyond monitoring works best when teams document this choice before editing.
The measurement must also be separated by engine and prompt type. A page can perform well for a basic definition yet fail for an evaluation prompt. Review Claude and Gemini citations alongside other tracked results before calling a tier successful or unsuccessful.
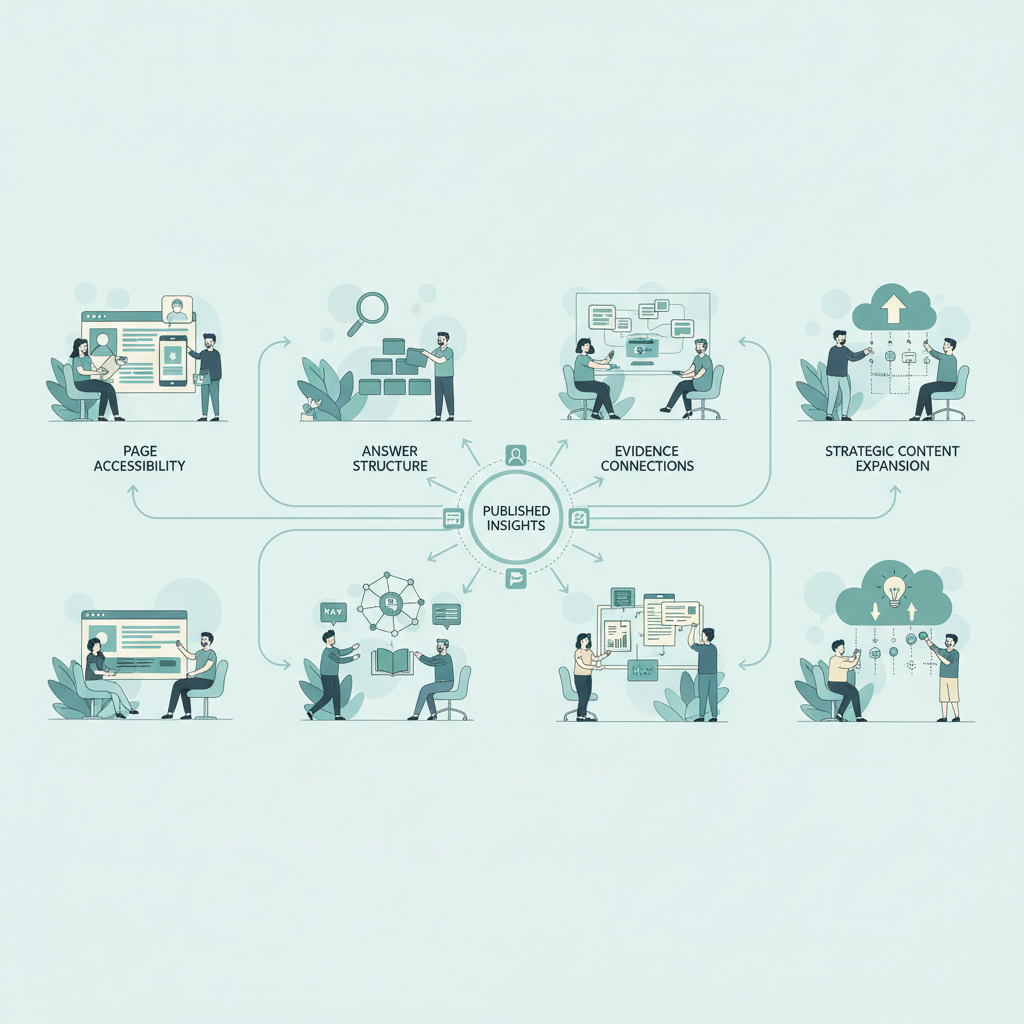
Measure Citation Lift Without Inventing Causality
A citation result is useful only when its denominator, prompt set, engine, and testing period are visible. A single favorable answer is an observation, not proof. Measure page-level outcomes consistently, and describe changes as evidence of association unless your test design supports a stronger conclusion.
Now, turn each tier into a repeatable experiment.
Measurement gives content optimization beyond monitoring its discipline, because every change can be traced to a specific baseline, test condition, and decision.
Freeze the target prompts, engines, locations, page URLs, and run cadence. Record repeated baseline results. Change one tier where possible, then rerun the same set and calculate citation rate as cited trials divided by eligible trials, multiplied by 100. That repeatability makes content optimization beyond monitoring interpretable over time.
| Measurement Field | What To Record |
|---|---|
| Prompt Set | Exact questions, intent, location, and version date |
| Engines | Each tested AI answer experience, reported separately |
| Page Outcome | Whether the target URL was cited and where |
| Change Log | Tier used, edit date, page version, and owner |
| Decision | Keep, revise, expand, or stop based on evidence |
Microsoft describes AI Performance as visible citation activity, not a measure of ranking, authority, or importance. That measurement distinction is essential: content optimization beyond monitoring should track citations, but it should not pretend citations alone explain revenue, trust, or long-term demand.
A practical baseline can begin with the daily mentions workflow, then mature into a fixed prompt library and a documented testing cadence. The discipline is what makes lift interpretable.
Put the Stack to Work with PageLens.ai
PageLens.ai helps marketing, growth, SEO, and content leaders move from a visibility report to a governed content optimization workflow. Start by maintaining a fixed prompt set, grouping findings by the four tiers, and assigning each change to an owner with a measurable completion criterion. The goal is not to produce more edits. It is to show which edits improve source eligibility, answer usefulness, and buyer coverage over time. For teams practicing content optimization beyond monitoring, PageLens.ai is most useful when one place is needed to turn prompt observations into an ordered content backlog, while retaining human review of every claim and source. Bring your existing measurement baseline, your priority pages, and the buyer questions that matter most. Then use the stack to decide whether the next move is a technical correction, a rewrite, a semantic connection, or a new page with your team, Book a demo.
FAQs on Content Optimization Beyond Monitoring
Use these concise answers to choose tiers, test citations, and apply markup responsibly. They preserve the framework’s core rule: diagnose the constraint, then measure each change.
Can I Skip Tiers?
Yes. Start with the diagnosed constraint, not a fixed sequence. Always retain factual verification, crawlability checks, and a stable measurement process for every page tested.
How Do I Measure Citation Lift?
Freeze prompts, engines, locations, and page URLs. Record repeated baselines, change one tier where practical, then report absolute citation-rate movement with dates and denominators for review.
Can Schema Alone Improve Citations?
No. Accurate markup can improve machine understanding, but it does not make a page useful, original, current, or guaranteed to appear as a cited source.
References
These sources support the factual claims and measurement principles used in this article. They include official platform documentation and current research, with research findings treated as directional evidence where the work is published as a preprint rather than as a universal performance guarantee.
Use them to verify the underlying claims and adapt the process to your own testing environment.