TL;DR
A governed operating model for prompt design, repeatable AI answer collection, QA, alerts, ownership, and executive reporting.
How Enterprise Teams Automate AI Brand-Mention Monitoring
Manual checks become expensive quickly. Using a U.S. private-industry benchmark of $87.69 per hour for management, business, and financial occupations, 15 hours of weekly checking represents $1,315.35 of labor before any reporting or follow-up work.
Enterprise AI Brand-Mention Monitoring automates approved prompts across relevant answer engines, retains every response and citation, normalizes results, validates data quality, and reports persistent changes to named owners. Reliable monitoring is not merely a platform feature. It is a governed operating model for repeatable evidence, investigation, and action.
This guide explains how to replace manual checks with Enterprise AI Brand-Mention Monitoring, from a cost baseline through rollout.
What Changes When an Enterprise Replaces Manual AI Answer Checks?
Manual checking is useful when a team is learning the questions buyers ask. It stops being sufficient when leaders need a comparable baseline, a defensible trend, or a response plan. Enterprise AI Brand-Mention Monitoring turns occasional checking into a measurement system with defined inputs, retained evidence, and accountable decisions.
Start by separating the cost of the habit from the capabilities required to replace it.
For a team spending 15 hours each week on manual checks, the six-month labor baseline is $34,199.10, calculated as 15 hours times $87.69 times 26 weeks. The annual equivalent is $68,398.20. Treat this as an external benchmark, not a substitute for Finance’s loaded internal rate.
| Approach | Repeatable Conditions | Evidence Retained | Best Use | Main Limitation |
|---|---|---|---|---|
| Manual Spot Checks | Rarely | Screenshots and notes | Exploratory research | No dependable baseline |
| Scheduled Monitoring | Yes | Runs, mentions, citations, trends | Ongoing reporting | Requires coverage validation |
| API Collection | Yes | Structured response objects | Controlled engine-specific collection | Requires engineering ownership |
| Custom Internal Pipeline | Fully configurable | Warehouse records and logs | Specialized integrations | Ongoing maintenance burden |
A credible Enterprise AI Brand-Mention Monitoring program documents why each method is used, where its evidence is stored, and which results are appropriate for leadership reporting. That distinction makes AI visibility tracking suitable for executive reporting.
What Does a Governed Monitoring Operating Model Look Like?
A durable Enterprise AI Brand-Mention Monitoring program has a lifecycle, not a sequence of dashboard clicks. It starts by defining what must be measured, preserves the evidence behind each result, and ends with a named action owner. That structure keeps reporting comparable when answer-engine behavior changes.
Use a seven-step workflow that connects measurement to action.
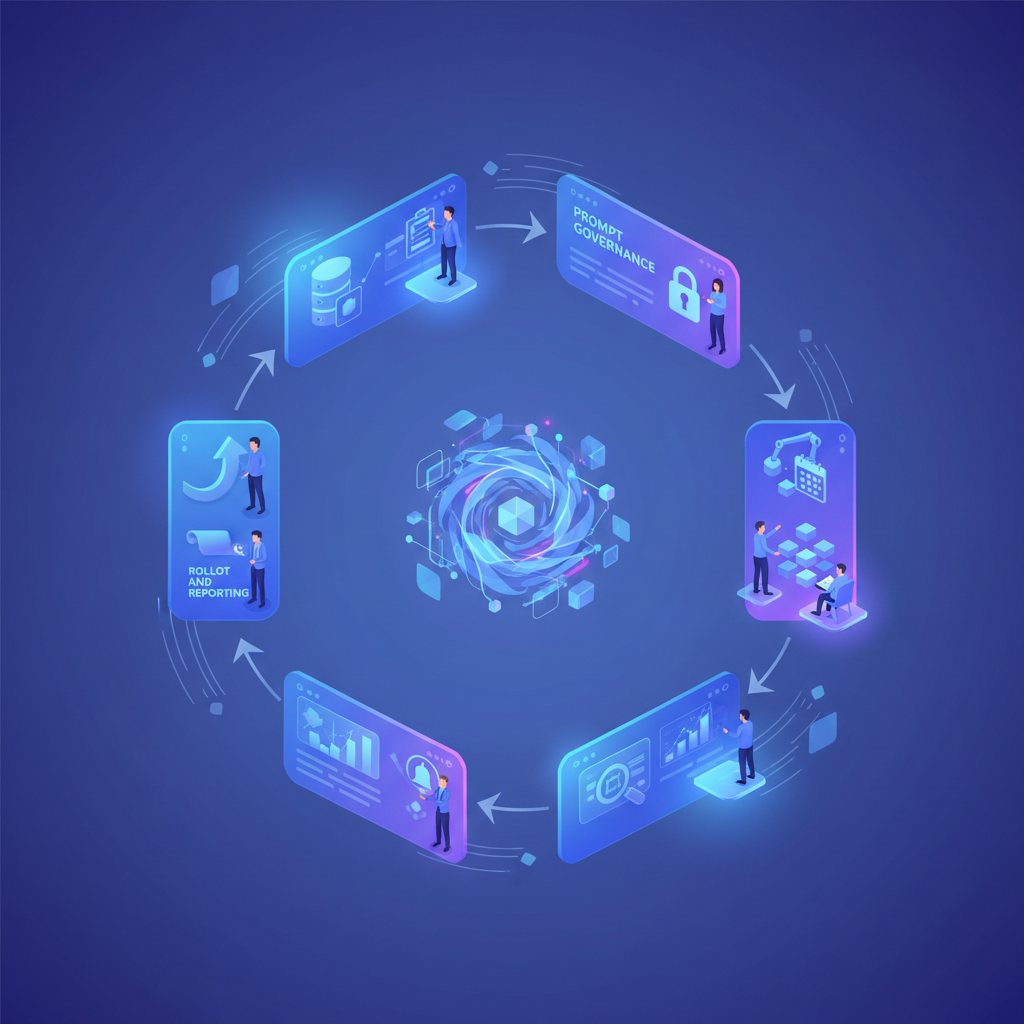
- Baseline: Select priority markets, audience roles, engines, and prompt families.
- Prompt Contract: Version each prompt, document its intent, and assign an approver.
- Scheduled Collection: Run prompts on a documented cadence and retain raw outputs.
- Normalization: Standardize aliases, citations, duplicates, and engine-specific formats.
- Quality Control: Validate classifications, failures, and unexpected schema changes.
- Metrics And Alerts: Measure trends, confirm persistence, and route material changes.
- Rollout And Reporting: Integrate dashboards, manage access, and expand only after pilot acceptance.
This model follows the logic of the NIST framework: govern the work, map the context, measure outcomes, and manage the response. Enterprise AI Brand-Mention Monitoring converts those principles into a practical measurement routine.
Which Prompts Belong in the Governed Set?
The best prompt set does not begin with the longest possible list. It begins with decisions the business needs to make, then maps prompts to buyer journey, audience, market, and language. Enterprise AI Brand-Mention Monitoring works when its prompt inventory is controlled enough to compare over time.
Build the prompt registry before you schedule collection.
Each approved prompt should record its buyer-journey stage, target role, market, language, engine, version, owner, approver, effective date, and reason for inclusion. Keep a separate experimental queue so untested wording never contaminates the core reporting baseline.
Use prompt families such as problem discovery, solution evaluation, product comparison, implementation planning, and renewal risk. Enterprise AI Brand-Mention Monitoring depends on prompt governance because changing the question changes the measurement. This is why prompt research deserves its own process rather than being treated as a renamed keyword list.
Answer behavior can vary as models and tools change. Official API guidance recommends pinned model versions and evaluations when consistency matters. Where model or mode is not visible, record that limitation rather than pretending the runs were identical.
What Data Makes a Run Reproducible?
A monitoring result is only as credible as the record behind it. Teams need enough context to reconstruct a run, inspect a disputed classification, and distinguish a true visibility change from a collector failure. Enterprise AI Brand-Mention Monitoring should treat raw answer records as evidence, not disposable intermediate data.
Capture the same core fields for every completed or failed run.
| Required Field | Why It Matters |
|---|---|
| Prompt Text And Version | Reconstructs the exact tested question |
| Engine And Available Mode | Identifies the answer environment |
| Run Date, Time, And Locale | Preserves temporal and geographic context |
| Raw Response | Supports review and parser QA |
| Citation URLs And Positions | Separates a citation from a text mention |
| Run Identifier | Traces retries, failures, and duplicates |
| Brand Dictionary Version | Reproduces mention classification |
| Collector And Parser Version | Explains measurement-system changes |
The strength of Enterprise AI Brand-Mention Monitoring comes from preserving this record across every run, including failures and retries. That makes it possible to revise an alias rule, reclassify a sentiment decision, or investigate a missing citation without rerunning history. The same evidence model supports multi-engine signals without forcing every answer engine into an artificial ranking system.
How Should Teams Normalize and Quality Check Results?
Normalization creates a common reporting language without erasing meaningful differences among answer engines. It should resolve known brand aliases and duplicate runs, while preserving raw output, source objects, and missing-data states. Enterprise AI Brand-Mention Monitoring fails when a parser quietly converts uncertainty into a confident metric.
Make the normalization rules explicit and versioned.
- Brand Aliases: Map official names, abbreviations, former names, and common misspellings to a reviewed entity.
- Generic References: Do not count category language as a brand mention without an approved rule.
- Duplicate Answers: Retain the original record, then flag retries and technical duplicates.
- Missing Citations: Distinguish no citation returned from citation extraction failure.
- Engine Formats: Preserve engine-specific source structures before mapping them to common fields.
- Quality Samples: Review a defined sample of automated classifications and log disagreements.
For Enterprise AI Brand-Mention Monitoring, normalization rules are part of the measurement contract. Logging must also respect security and privacy. OWASP logging advises protecting log integrity, centralizing monitoring, and avoiding unnecessary sensitive data.
Which Metrics Belong in an Executive Dashboard?
Executive reporting should show what changed, where it changed, and whether the measurement was complete enough to trust. It should not collapse different answer engines into one fictional rank. Enterprise AI Brand-Mention Monitoring needs clear denominators, segments, and a visible data-quality layer beside every outcome metric.
Report a small set of decision-ready metrics, segmented by market and prompt family.
| Metric | Definition | Executive Question |
|---|---|---|
| Mention Rate | Valid runs mentioning the brand divided by valid completed runs | Are we appearing? |
| Citation Rate | Valid runs citing an owned domain divided by valid completed runs | Are trusted sources appearing? |
| Share Of Voice | Brand mentions divided by all identified brand mentions | How visible are we within the defined set? |
| Prominence | First appearance or recommendation-list placement | How strongly are we presented? |
| Sentiment | Reviewed classification of exact brand language | How are we described? |
| Response Consistency | Repeated valid runs with the same outcome | Is the result stable? |
| Data-Quality Coverage | Completed runs divided by scheduled runs | Can this trend be trusted? |
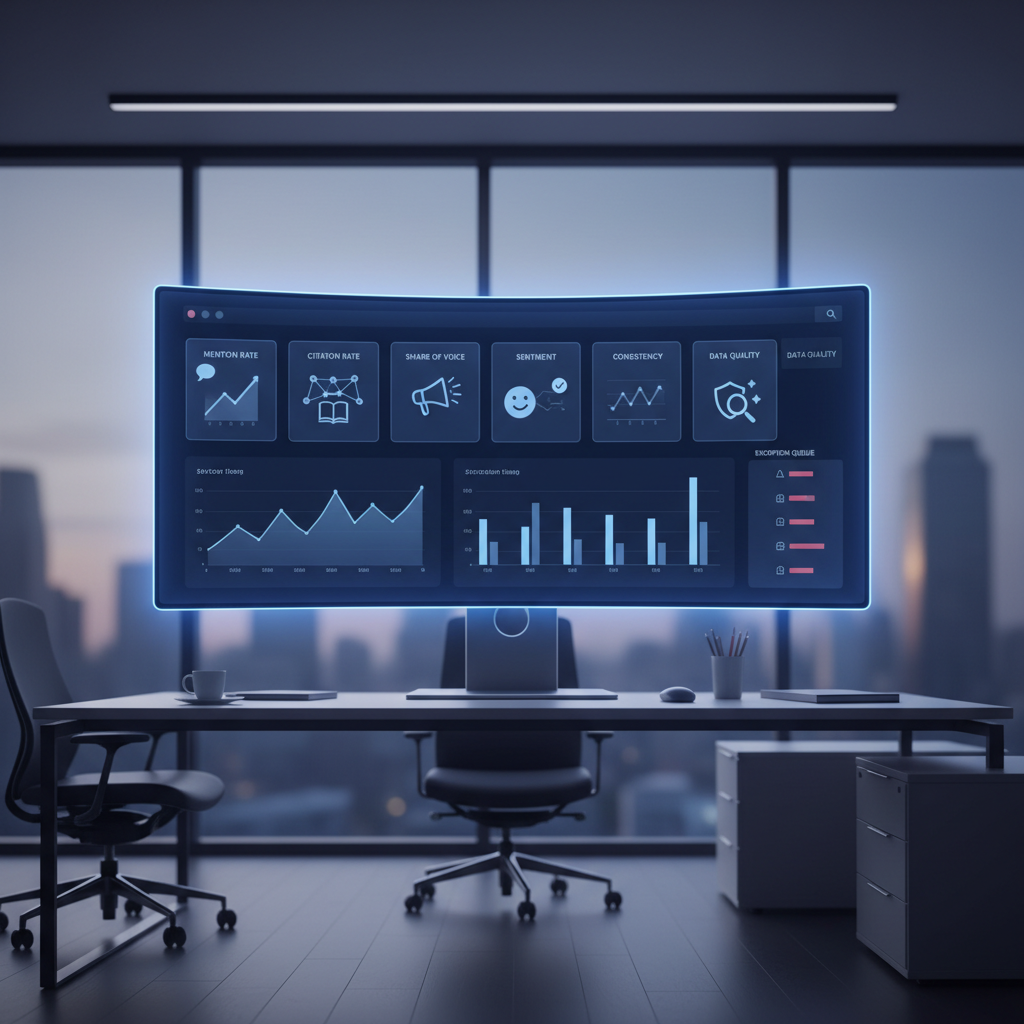
Use Enterprise AI Brand-Mention Monitoring metrics carefully. ChatGPT search responses can expose inline citations or a Sources panel, according to its search documentation. A cited source, a text mention, and a favorable recommendation are related but different signals, so the dashboard should never merge them without labels.
For teams that need language-level review, sentiment architecture can help separate automated classification from the evidence a reviewer can inspect.
When Should an Alert Trigger, and Who Acts?
An alert should identify a change worth investigating, not produce noise every time an answer varies. Effective Enterprise AI Brand-Mention Monitoring uses persistence rules, data-quality safeguards, and a clear escalation path. A one-run anomaly is usually a review signal. A critical factual or legal misstatement may require immediate action.
Set the decision path before the first executive report.
Change Detected
├─ Collection Failure Or Format Change?
│  └─ Data Owner Investigates, Visibility Conclusion Paused
├─ Critical Factual, Safety, Or Legal Misstatement?
│  └─ Immediate Escalation To Communications And Legal Owners
├─ Change Persists Across Approved Repeat Runs?
│  └─ Continue Monitoring And Record As Noise
└─ Material In A Priority Market Or Prompt Family?
   ├─ Weekly Review Queue
   └─ Open Action, Assign Owner, Report Resolution
Use two independently scheduled valid runs as a practical confirmation rule for noncritical alerts after the pilot establishes normal variance. Suppress alerts during known outages, prompt-version changes, incomplete coverage, or parser failures.
| Activity | Marketing Or SEO | Data And Analytics | Regional Lead | Legal Or Privacy | Executive Sponsor |
|---|---|---|---|---|---|
| Prompt Approval | A/R | C | C | C | I |
| Collection And QA | C | A/R | I | I | I |
| Brand Dictionary Review | A/R | C | C | I | I |
| Critical Escalation | R | C | C | A/R | I |
| Executive Reporting | R | R | C | I | A |
A mature Enterprise AI Brand-Mention Monitoring practice keeps alerts connected to evidence, an accountable owner, and a documented resolution. The ICO audit guidance emphasizes accountability and audit trails.
Use content optimization only after monitoring evidence is stable enough to prioritize changes with confidence.
Should You Build or Buy, Then How Do You Roll Out?
Build versus buy is not a feature checklist. It is a decision about coverage, auditability, integration fit, security review, maintenance capacity, and commercial terms. Enterprise AI Brand-Mention Monitoring should be bought when a governed product meets the requirements. It should be built only when differentiated requirements justify durable internal ownership.
Score the options against the operating model, not against a demo alone.
| Criterion | Buy Favors | Build Favors |
|---|---|---|
| Engine Coverage | Supported engines meet the required scope | Collection requirements are unusual |
| Auditability | Raw exports and run evidence are available | Full record control is mandatory |
| Integrations | Existing BI, warehouse, and SSO fit | Internal data platform already owns the workflow |
| Security Review | Retention and access controls pass review | External architecture is not permitted |
| Maintenance Burden | Vendor manages format and product changes | Funded engineering ownership exists |
| Commercial Terms | Data rights and exit terms are acceptable | Internal cost is justified long term |
For Enterprise AI Brand-Mention Monitoring, the decision should include ownership after launch, not only capabilities during evaluation. Roll out with one market, one audience, and a limited set of priority prompt families. Validate raw answers against normalized results, confirm dashboard access rules, test the alert runbook, and establish a weekly operating review plus monthly leadership readout.
- Pilot Scope: Limit engines, markets, and prompt families until data quality is proven.
- Validation: Compare raw outputs with normalized records and investigate mismatches.
- Access Control: Define role-based viewing, exports, retention, and reviewer permissions.
- Expansion Criteria: Require stable schema, accepted QA, tested escalation, and stakeholder adoption.
- Procurement Review: Confirm security, integration, data rights, and maintenance ownership.
An Enterprise AI Brand-Mention Monitoring rollout begins with a limited baseline and expands only after the team can trust the evidence. Use a deployment checklist during evaluation.
Put PageLens.ai into a Governed Workflow
PageLens.ai belongs in the conversation when marketing, growth, SEO, and content leaders need to operationalize an approved monitoring program. Enterprise AI Brand-Mention Monitoring begins with decision requirements: markets, prompt families, answer engines, roles, retention expectations, executive views, and integrations. Bring the people who own approvals, data quality, investigations, and reporting into the evaluation.
Use a limited pilot to test the operating model before a broader commitment.
A useful evaluation asks whether Enterprise AI Brand-Mention Monitoring preserves evidence, supports controlled prompt changes, surfaces meaningful exceptions, and fits security and reporting practices. It also asks what remains the team’s responsibility after implementation, because governance cannot be outsourced. Explore the deployment requirements, agree pilot acceptance criteria before procurement, and choose a rollout that gives leadership a trustworthy baseline. Test exports, permissions, audit evidence, stakeholder adoption, and the recurring operating cadence before expanding coverage with the PageLens Platform. Book a demo
FAQs on Enterprise AI Brand-Mention Monitoring
How Do Enterprise Teams Automate AI Mention Tracking?
Enterprise AI Brand-Mention Monitoring schedules approved prompts, saves raw answers and citations, normalizes brand data, quality-checks collection, alerts on persistent changes, and assigns owners for action.
What Metrics Should an Enterprise AI Visibility Dashboard Include?
Enterprise AI Brand-Mention Monitoring should track mention rate, citation rate, share of voice, prominence, sentiment, response consistency, and data-quality coverage across approved reporting segments each week.
How Do You Replace Manual ChatGPT and Perplexity Brand Checks?
Enterprise AI Brand-Mention Monitoring replaces manual checks with scheduled versioned prompts, retained raw responses, citation extraction, normalization rules, QA sampling, persistence alerts, and owner-led operating reviews.
Should an Enterprise Build or Buy AI Answer Monitoring?
Enterprise AI Brand-Mention Monitoring is bought when coverage, evidence, integrations, security, and commercial terms fit. Build only when differentiated requirements justify funded, long-term engineering ownership.
What Data Fields Are Required for Reproducible Monitoring?
Enterprise AI Brand-Mention Monitoring requires prompt, version, engine, available mode, timestamp, locale, raw response, citations, run identifier, brand dictionary version, and parser version for auditability.