TL;DR
At PageLens.ai, we judge enterprise AI visibility platforms by whether they turn answer evidence into owned, approved, and retested work. This guide explains the detect, diagnose, assign, fix, and retest loop, then gives enterprise teams a procurement scorecard, governance criteria, and a practical way to test a platform before buying.
Which Enterprise AI Visibility Platforms Drive Action?
AI search has become a practical marketing surface, not a future bet. In a 2025 survey of 1,437 U.S. adults, 60% said they had used AI to search for information, according to the AP-NORC poll.
At PageLens.ai, we judge enterprise AI visibility platforms by whether they preserve answer evidence, identify the page or source needing attention, assign a named owner, route an approved fix into existing workflows, and retest the same prompt. Without that chain, a score is monitoring, not an operating system. We cover the evidence, handoffs, governance, and procurement test that make the difference.
What Makes an Enterprise AI Visibility Platform Actionable?
An actionable platform does not begin and end with share of voice. It starts with a defined buyer prompt, records what an answer engine actually returned, and carries that evidence through a decision someone can own. The goal is not to make a dashboard look busier. It is to make the next decision easier to defend.
This matters because answer engines are not a fixed rankings database. Google explains that AI search experiences can use query fan-out, which runs related searches across subtopics and can surface different supporting links from conventional results. That makes a stored answer, source list, locale, date, and prompt definition essential evidence, not optional reporting detail. See our guide to multi-engine signals for the measurement fields worth keeping together.
| Stage | Question To Answer | Required Evidence | Exit Rule |
|---|---|---|---|
| Detect | Did an answer change or reveal a gap? | Prompt, engine, locale, time, raw answer | Repeatable observation |
| Diagnose | What could explain the gap? | Cited sources, owned pages, technical checks, exact wording | Prioritized hypothesis |
| Assign | Who can make the next decision? | Named owner, dependency, approval route | Accepted work item |
| Fix | What will change in public? | Approved brief, ticket, or communications action | Published or deployed change |
| Retest | Did the comparable answer change? | Same cohort, date range, outcome record | Changed, unchanged, or inconclusive |
| Govern | Can the team audit the process? | Access, retention, history, and decision log | Procurement-ready record |
We treat every stage as a separate state. A detected absence is not a diagnosis, a recommendation is not an approved change, and a published page is not verified visibility. That separation keeps optimistic interpretation from becoming reporting.
How Do Teams Detect and Diagnose a Gap?
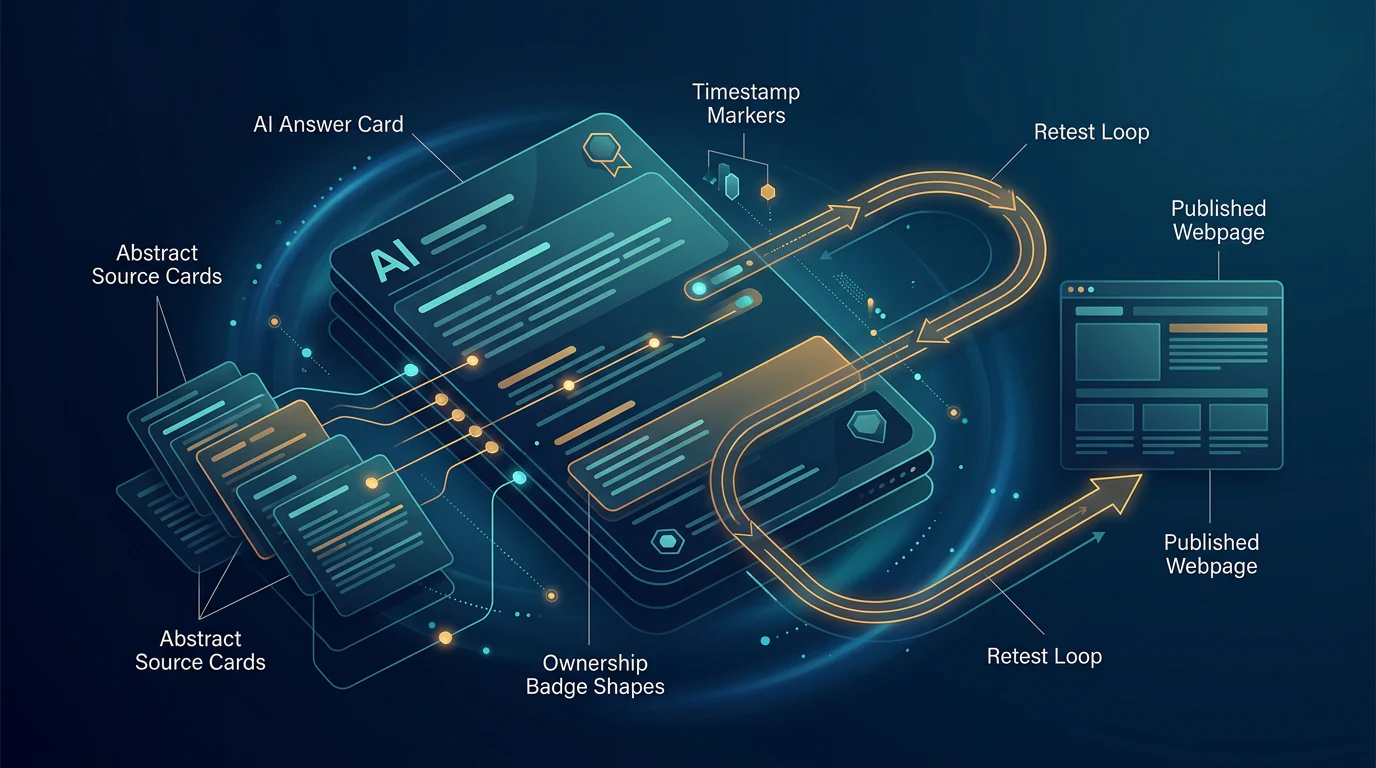
Detection becomes useful only when the underlying answer remains inspectable. We capture the prompt and response first, then identify the sources, brand language, and surrounding context that make a result worth investigating. When answers include web citations, the response can retain URL-citation annotations that identify the linked source and its location in the answer, as described in the OpenAI citation docs.
How Do You Distinguish a Trend from Answer Volatility?
We start with a controlled cohort. That means keeping buyer prompts, engines, language, location, classification rules, and timing stable enough to compare like with like. A single response may reveal an opportunity, but it cannot establish a durable market position.
For every run, we separate eligible answers from missing or unusable outputs. We also retain the exact language describing the brand, rather than reducing sentiment to an unexplained number. That makes it possible to see whether a change reflects a new recommendation, a different source mix, or merely a different answer shape. Our approach to citation sources focuses on that answer-level evidence.
How Do You Diagnose the Type of Gap?
A visibility gap can be technical, editorial, reputational, or distribution-related. Technical evidence may show that an important page is blocked, inaccessible, thin in visible text, or inconsistent with its structured data. Editorial evidence may show that an owned page does not answer the buyer’s actual decision. Reputational and distribution evidence may reveal recurring language or trusted third-party sources that shape the answer more directly.
Google’s guidance is clear about the boundary: a page must be indexed and eligible to appear with a snippet to be eligible as a supporting link in its generative search features, but eligibility does not guarantee that it will be served. That is why we pair answer monitoring with a documented investigation, instead of treating a single score as a root cause.
What Evidence Makes a Diagnosis Credible?
We want enough evidence for another team member to challenge the conclusion. That record should include the answer, cited URLs, the affected owned page, the relevant sentence or claim, diagnosis confidence, and the conditions under which the answer was captured.
A platform should be able to say, “Here is what changed, here are the sources involved, and here is why this action is being proposed.” If it can only say that visibility fell, it has identified a signal but not produced a usable diagnosis.
How Do Teams Assign, Fix, and Retest a Gap?
After diagnosis, the workflow becomes an operating model. SEO, content, communications, product marketing, legal, and engineering may all touch the same gap, but they should not receive the same vague alert. Each team needs a scoped decision, supporting evidence, and an acceptance criterion.
We align this with the NIST framework’s emphasis on governing, mapping, measuring, and managing AI-related risk over time. Its AI risk framework calls for documented measurement and prioritised responses, which is a useful discipline even when the risk is inaccurate brand representation rather than model deployment.
Who Owns the Next Action?
Technical findings belong with engineering or technical SEO. Missing buyer explanations usually belong with content operations and product marketing. Incorrect external framing may require brand communications and subject-matter review. The platform’s job is to make the handoff specific enough that the owner can accept, reject, or refine it.
We use an AI visibility audit to create that handoff. Each finding should identify the affected prompt, evidence, proposed action, owner, dependencies, approval path, and retest date.
What Should a Useful Ticket or Brief Contain?
A useful work item includes the finding ID, prompt, answer snapshot, cited sources, diagnosis type, target page or asset, named owner, decision deadline, and acceptance criteria. It should also state what would make the diagnosis wrong.
For content work, the brief should identify the buyer question being missed, the source evidence to address, the product or expert review needed, and the page that will be monitored after publication. For technical work, it should identify the observable condition and the production validation required. That distinction keeps a visible answer gap from becoming an untested implementation assumption.
When Does a Retest Count as Verification?
A retest is meaningful only when it compares the same defined cohort. We rerun the prompt set under documented conditions, record answers and sources again, and classify the result as changed, unchanged, or inconclusive.
That standard protects teams from claiming that a new page caused an answer change when other inputs may have moved. It also helps leaders see whether the effort improved recommendation language, citation presence, source quality, or simply created a clearer diagnostic record for the next cycle. Teams that need formal access, retention, and approval controls can use governed execution to make those handoffs inspectable.
Which Enterprise Platform Model Fits Your Workflow?
There is no universal best platform because enterprises buy different operating models. Some need broad monitoring and exports. Others need content workflow, governed approvals, technical handoffs, or a managed execution layer. The right comparison starts with what evidence must reach the person accountable for the next action.
Before a demo, agree on the buyer prompts, markets, languages, engines, retention needs, and internal systems that matter. Then ask vendors to demonstrate the complete journey using one real gap. Do not accept a feature tour as proof that work can move from answer evidence to verified remediation. Our guide to AI search rankings explains why a repeatable prompt set matters before any comparison begins.
| Platform Model | Evidence To Require | Diagnosis Depth | Execution Path | Governance And Integrations | Pricing Model To Test |
|---|---|---|---|---|---|
| Monitoring-First | Raw answers, citations, context, history | Prompt and source observation | Export or manual handoff | API, warehouse export, BI access, retention | Prompts, engines, seats |
| SEO Stack Add-On | AI data separated from conventional search metrics | Content and technical signals may be separate | Existing SEO workflow | Analytics, ticketing, role controls | Base subscription plus add-on |
| Content Workflow Platform | Evidence linked to briefs and pages | Editorial emphasis | Brief, approval, publish, review | CMS, project management, version history | Seats, outputs, sites |
| Managed Service Model | Methodology and evidence pack | Human-led diagnosis | Strategy and scoped delivery | Reporting access, handoff, service scope | Retainer or project scope |
| Closed-Loop Execution Model | Prompt-to-retest evidence trail | Cross-functional diagnosis | Tickets, approvals, remediation, retest | APIs, webhooks, BI, access controls | Subscription plus defined services |
A scorecard stops the evaluation from becoming a collection of attractive screenshots. We recommend weighting evidence and execution more heavily than interface preferences, because those are the capabilities that determine whether a discovered gap can become accountable work.
| Procurement Criterion | Weight | What To Verify In A Demo |
|---|---|---|
| Evidence Quality And Reproducibility | 20 | Raw answers, sources, dates, locales, and missing-output rules |
| Diagnosis Specificity And Confidence | 15 | Clear distinction between observation and hypothesis |
| Execution And Ownership Workflow | 20 | Tickets, briefs, approvals, dependencies, and accountable owners |
| Retesting Discipline | 15 | Comparable cohorts and changed, unchanged, or inconclusive states |
| Governance And Security Evidence | 10 | Access controls, retention, regional scope, and audit history |
| Data And Workflow Integrations | 10 | API, webhooks, data warehouse, BI, and work-management connections |
| Pricing Predictability | 10 | Contract limits, prompt volume, engines, users, and services |
For enterprise procurement, governance is not a final checkbox. Privacy principles such as data minimisation, storage limitation, security, and accountability should shape what prompt and answer data is retained, according to the ICO guidance. Use this discipline to keep commercial reporting tied to inspectable evidence.
A proper review should also establish whether visibility movement reflects lost citations, a changed answer pattern, or a different prompt cohort. That is the purpose of a focused citation drop audit, not another blended score.
Why Choose PageLens.ai for Actionable Visibility?
At PageLens.ai, we built our workflow for teams that need more than a chart. We capture defined buyer prompts and answer evidence, connect recurring gaps to cited sources and practical content decisions, and keep approval separate from execution. That gives SEO, content, brand, and communications leaders a shared record of what changed, who owns the next step, and what must be retested.
We also keep the boundary honest. We can turn reviewed evidence into content actions and monitoring, while technical deployments require developer approval and independent production validation. Our public plans describe daily tracking and an Enterprise plan with 200 tracked prompts, 1,400 AI answers per day, and seven listed answer engines. If your team needs a governed route from answer evidence to action, bring us the prompts that matter. We will show the evidence trail before anyone is asked to act, then Book a demo.
FAQs on Enterprise AI Visibility Platforms
What Are the Best AI Visibility Software for Marketers?
The best software preserves prompts, answers, citations, sentiment, and changes. A share-of-voice audit helps, but marketers still need a prioritized action, named owner, approval path, and comparable retest.
What Is the Best AI Visibility Platform?
The best platform fits your operating model, preserves inspectable evidence, routes validated work to accountable teams, supports governance, and proves outcomes through comparable repeat testing.
Which AI Visibility Tools Fit Enterprise SEO Teams?
Enterprise SEO teams need cross-engine answer records, citation analysis, technical handoffs, controlled sampling, exportable data, access controls, and approval workflows that connect findings to production work.
What Is the Best AI Visibility Tool for Enterprise Brands?
Enterprise brands should favor platforms that document answer language, source context, ownership, approvals, regional settings, and retesting, rather than relying on a blended visibility score.
What Is the Best AI Visibility Audit Tool?
The best audit tool separates observed answer outcomes from technical evidence, identifies a prioritized hypothesis, assigns next steps, and records whether comparable retesting changed results.